Prime Resources
featured articles
Cutting Through ProdSec Noise
Prioritizing Vulnerabilities by Context Driven Attack Paths, Not Severity Score
Open any vulnerability dashboard right now and you'll see the same thing every security team sees: more findings than anyone could review in a lifetime, ranked by severity scores that all cluster near the top. Roughly 48,000 new CVEs were published in 2025 alone, and the average program has bandwidth to remediate somewhere between 10 and 15 percent of its backlog in a given month. That gap between what gets found and what gets fixed isn't a staffing problem. It's noise, and it's been mistaken for a risk picture for long enough that most teams have stopped questioning it.
Vendors have started layering exploitability and reachability signals on top of severity scores, flagging whether a CVE has a known exploit in the wild or whether the vulnerable function is actually called by application code. That's a real step past CVSS alone, and it does cut some findings out of the queue. But exploitability and reachability answer "can this be exploited," not "does it matter here." A reachable, exploitable vulnerability in an internal tool with no sensitive data behind it is a different risk than the identical vulnerability in a service with a direct path to payment data, and exploitability scoring alone can't tell those two apart. Without the business and architectural context to make that distinction, exploitability and reachability data just re-sorts the same pile into a slightly different order. It doesn't reduce it.
Where All This Noise Comes From
Noise doesn't come from one bad scanner. It comes from the fact that every scanner you add reports its own findings in isolation, with no view of whether anything it flags actually connects to anything else. SAST grades code. SCA grades dependencies. Secret scanning grades commits. Each one is doing its job correctly, and each one is contributing its own independent stream of severity-ranked findings to a backlog that was already too large before it showed up.
That fragmentation was survivable when code shipped at human pace. AI coding agents have removed that constraint, and the backlog is growing with it. A developer opens a handful of pull requests a day; an agent working in the background can open dozens, and every one of them triggers its own pass from every scanner in the pipeline. The noise problem stopped being something a team could plan around once a quarter and became something that compounds with every commit an agent makes, which means the case for reducing it is no longer theoretical. It's urgent, and it gets more urgent by the day.
Adding tools to cover more of the stack feels like progress, and in a narrow sense it is. But it also means the noise compounds. Four scanners each reporting cleanly on their own slice of the product doesn't add up to a quieter picture of risk. It adds up to four separate streams of findings, none of which know about the other three, and that isolation is exactly what produces false positives and false confidence in the same breath. A scanner with no view of the environment has no way to know a downstream control already neutralizes what it just flagged, so it reports a real finding as urgent when it isn't. The opposite failure is just as common: without understanding how the surrounding system actually behaves, a tool can't verify whether a vulnerability it found is reachable in an actual attack path, which means genuine risk gets buried in the same pile as the noise around it.
Why More Noise Doesn't Mean More Security
The instinct is to sort the noise by severity and work top-down. That fails because severity measures how bad a vulnerability could theoretically be, not whether it's reachable, exposed, or exploitable in this specific environment. Two findings with identical CVSS scores can carry completely different risk depending on what's around them: one sits behind three layers of controls, the other has a direct path to production. A backlog sorted by severity alone treats those as the same problem, which is exactly why teams burn remediation capacity on findings that were never going anywhere while genuinely dangerous ones sit untouched further down the list.
Cutting Through the Noise Starts with One Question
Cutting through that noise isn't a matter of triaging faster or tuning the scoring model harder. It requires asking a different question of every finding, one severity scores were never built to answer: is this part of a path an attacker could actually walk right now, given what it connects to. And more importantly, how feasible is this path? If an exploit requires Tom Cruise to dangle dramatically from the ceiling, it’s unlikely to be prioritized by attackers. In other words, there is no simple solution that relies on a single score…which is exactly why context matters!
That's an execution-path question, not a severity question, and it changes what "important" means. A CVSS 9.8 sitting on a service with no route to anything sensitive isn't urgent, whatever the score says. A medium-severity finding sitting on a component that connects straight to a trust boundary might be the most important thing in the backlog. Severity describes a finding in isolation. An execution path describes what happens once you stop looking at scores and start focusing on the real impact to the business and how exposed the vertical to that impact.
What's Left When You Filter for Execution Paths
Run that filter honestly and the backlog doesn't just get shorter, it changes shape entirely. What's left isn't a smaller version of the same list sorted the same way. It's a small, specific set of findings that are reachable and chained together into something an attacker could actually use, the kind of path where a component that passes its own scan cleanly still turns out to be one link in a route to something that matters.
Building a Practice Around Signal, Not Volume
None of this is an argument for buying another scanner. Another scanner adds another stream of severity-ranked findings, which is exactly the problem, not the fix. What's needed is something that doesn't produce its own isolated list at all: a way of seeing the product as one connected system, where a finding is judged by what it opens up rather than scored and filed on its own.
SAST, SCA, and secret scanning were built to grade their own slice of the product well, not to reason across slices, and no amount of tuning changes that. What's missing is a layer above all of them, one that holds architecture, data flows, and access paths in view together and asks the question none of the individual scanners can: does this finding sit on a path an attacker could really walk, given everything else true about this product right now.
The Elephant in the Room: Developer Alert Fatigue
The noise problem doesn't stay in security's backlog. Every finding that reaches a developer without context asks them to stop and chase down whether it's real, and often it isn't: a downstream control already handles it, the path doesn't exist, the function isn't even called. After enough of those empty chases, the rational response isn't more diligence. It's discounting the next finding, and the one after that.
That erosion is the real cost. It isn't just inefficient for security teams triaging a backlog. It teaches developers, correctly, that most of what lands in their queue isn't worth their time, which means the findings that actually matter now have to fight through that learned skepticism to get acted on at all. The fix isn't more findings or sterner tickets. It's surfacing only what's already been checked against the path it would need to travel.
What This Means for Security Leaders
The measure of a good vulnerability management practice was never how many findings you closed this quarter. It's whether what's left in front of your team, after the noise is filtered out, is actually worth their time. A shorter list sorted by the same broken signal isn't progress. A list built from real execution paths, however short, is.
At Prime, this is the case for correlating findings against real execution paths across the whole product rather than triaging them one severity score at a time, so what reaches your team is what an attacker could actually walk, not everything a scanner happened to flag.
Ready to see what's left once the noise is filtered out? Learn more at primesec.ai.
Software Security Needs a New Unit to Review
For the last decade, the pull request has been the moment a developer's work paused long enough for someone else to look at it. That pause is what turned the PR into a checkpoint. A reviewer read the diff and checked it for whatever could go wrong: bugs, broken business logic, security holes. Nobody designed the PR to be a security control. It became one because it was the last place in the software lifecycle where a person reliably paid attention before code shipped.
Now agentic development is breaking the math that made the diff work. PRs are getting bigger and more frequent at the same time, and the pause they run through hasn't gotten any longer. The unit of review is shifting under security's feet.
Before anyone scanned PRs, security tools ran against whole repositories, and compliance programs accepted that as review. The results were unusable: thousands of noisy findings and no way to tell which ones mattered. So the industry moved down to the diff. It was the easiest unit to work with, not the right one.
The PR is changing. Drastically.
Look at what a pull request is actually made of: a diff, a comment thread, and an approval button. None of it was ever the control. It was just tooling built for the moment someone paused to review the work. The pause survived on three conditions. PRs stayed small enough to read closely. Rare enough that every one of them got read. And the review produced a handful of issues that a developer will actually fix.
Agentic development is killing all three at once. Cursor's enterprise data shows average PR size more than doubling, with volume up another 25% on top. Mega PRs, 1,000 lines or more, are now routine. A Microsoft study of Claude Code and GitHub Copilot CLI users found adopters merging roughly 24% more PRs, hitting 50% in heavy-use weeks and holding there for four months. And bigger PRs carry more issues per review, pushing every comment thread past the point where developers stop reading it.
Any one of these would strain a review built around a careful pause. Together they take away everything it needed: time per PR, few enough PRs to give each one that time, and findings scarce enough to get fixed.
What's actually inside all those new PRs
Volume is only half the problem. The other half is what's landing inside each PR. CodeRabbit's analysis of AI-co-authored pull requests found they carry roughly 1.7 times more issues than human-only PRs, including 1.5 to 2 times more security-relevant findings like improper credential handling and insecure object references. High-issue outliers cluster in AI-assisted work. So a reviewer doesn't know which PR needed the slow read until they've already skimmed past it.
Compliance programs accept PR approvals as evidence that changes were reviewed before deployment. Today, the audit trail looks exactly like it did three years ago. What's changed is what that approval means. It used to mean someone read the code. Now, on a 1,500-line agent-written PR that arrived with six others that morning, it mostly means the person ran out of reasons to keep it open. The requirement is still being met on paper. Whether real security is happening underneath is a separate question, and no audit is built to ask it.
The unit was always a proxy
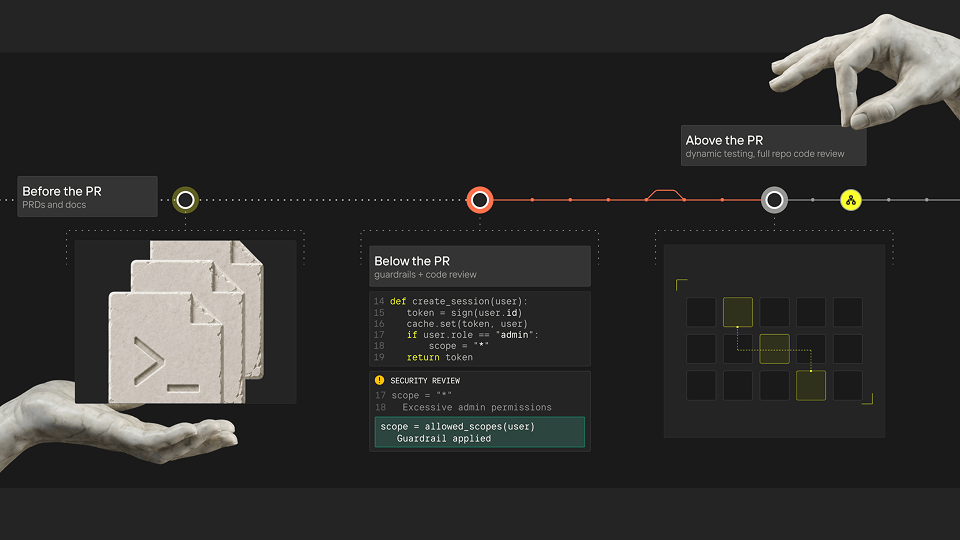
Once you see the PR as a stand-in for attention rather than a control in its own right, the question changes. Scaling review to handle more, bigger PRs is the wrong project. The real question is where that attention needs to live now that it can't all sit in one checkpoint.
Some of it belongs below the PR, where an agent makes decisions in real time and context can be applied before a diff exists. Some belongs above it, at the repository level, because a vulnerability spread across several small, reasonable PRs never shows up in any single diff. And some belongs before the PR entirely, in the architecture and design decisions that shape what an agent, or a developer, can build in the first place.
The repository level is the one that should give people pause, because the industry has been there before. Repo-wide analysis is where this story started, and it collapsed under its own findings. But that was a context problem, not a level problem. The tools flagged patterns without knowing what was reachable, what was exploitable, or what mattered to the product. Analysis that traces attack vectors and validates exploitability before it surfaces anything produces the one thing the old scanners never could: a short list. Five findings a developer will actually fix, with a risk score that is attached to a product. The comment-count condition, restored at the level the industry abandoned.
So PR reviews are dead? Right? Right?
No, PR reviews aren't dead. The pause they measured is.
Reviews stay in the program as one place security happens, not the primary one. Attention has to live where decisions live now: in the design before code exists, in the code as it's written, in the repository as it evolves. This is what we do at Prime, that's the architecture: review the design, guard the code, trace attack vectors across the repo, dependencies, and cloud continuously.
Black-Box Pentesting Gives Attackers the Advantage
For years, black-box penetration testing has relied on a simple premise: simulate an attacker who knows nothing about the system. The tester starts outside the application, discovers endpoints and functionality, infers architecture, and gradually builds an understanding of how the product works.
That assumption is outdated.
A serious attacker already has more information than the traditional black-box model assumes. Source code routinely leaves organizations through compromised insiders, contractors, repositories, legitimate access obtained under false pretenses, and AI-assisted development workflows. Source secrecy is no longer a strong foundation for offensive security.
If applications need to remain secure when an adversary understands how they work, testing needs to begin from the same vantage point. That is attacker parity.
Source code leaves through ordinary access
Source-code theft does not require a dramatic breach.
The North Korean IT worker campaign illustrates the problem. The FBI has warned that DPRK IT workers use false identities to obtain legitimate employment with U.S. companies and then use that access to steal proprietary information. In January 2025, the FBI specifically warned that workers had held stolen source code and other proprietary data for ransom.
Google Threat Intelligence has documented the same campaign at significant scale. The important security lesson is how access is obtained. An attacker hired under a false identity receives credentials, repository access, internal communications, and the same development environment as other employees. From the application's perspective, that access is legitimate.
AI-assisted development creates another path. Developers now work across coding assistants, model APIs, IDE extensions, autonomous agents, and third-party development services. When proprietary code is submitted to an external AI service, that service becomes part of the system trusted with the code. NIST's Generative AI Profile identifies data privacy, information security, third-party components, and data governance as areas organizations need to manage when deploying generative AI.
Source confidentiality is a weak assumption for an offensive security strategy.
Black-box testing assumes attacker ignorance
A black-box tester spends part of every engagement reconstructing information the engineering organization already possesses. They discover APIs, map routes, infer trust boundaries, experiment with authentication flows, and probe application behavior to understand the architecture.
That work is useful when the objective is to measure what an outsider discovers from an exposed application. It is a limited model of what a capable adversary does.
Source access changes the economics of attacking an application. Reconnaissance is faster, hypotheses are easier to form, and security controls are inspected directly instead of inferred through trial and error. Authorization logic, hidden endpoints, dependency behavior, and implementation assumptions all become easier to investigate.
The attacker spends more time searching for exploitable weaknesses while the black-box tester spends valuable engagement time rediscovering how the product works.
We already accept this model with open-source software. Security controls in an open-source application must withstand attackers who can inspect the implementation. Proprietary applications deserve the same standard.
White-box testing creates attacker parity
Defenders already possess an extraordinary amount of useful security context. They have the source code, architecture, security requirements, dependencies, deployment model, and historical design decisions.
White-box penetration testing puts that context to work.
A tester who understands the implementation moves directly into deeper questions about exploitability. They trace authorization logic across services, follow data through trust boundaries, examine how security controls are implemented, and identify places where implementation differs from design intent.
That context also makes it easier to investigate attack paths rather than isolated findings. A minor authorization weakness becomes critical when combined with a particular identity path or cloud configuration. Source code provides only part of that picture. Effective Product Security testing also needs architectural context, identity, infrastructure, dependencies, and application behavior.
A capable attacker uses whatever information they obtain. Defenders should use the information they already own.
Attacker parity must continue as the product changes
A white-box assessment still represents a point in time. The application starts changing again as soon as the engagement ends.
New code lands, dependencies change, APIs evolve, infrastructure is modified, and authorization logic gets refactored. AI coding tools and development agents have accelerated software production and increased the volume of changes security teams need to understand.
Attackers keep studying the product as it evolves. Offensive security needs the same continuity.
Continuous white-box pentesting preserves application context and repeatedly evaluates what is actually exploitable as the product changes. At Prime, that means connecting code with architecture, dependencies, cloud resources, application behavior, security decisions, and attack paths so testing starts with the context required to investigate meaningful risk.
Black-box testing still has a role
Black-box testing remains useful for understanding what an unauthenticated or opportunistic outsider discovers. It tests externally observable attack surface and exposes weaknesses in authentication, configuration, discovery, and application behavior.
It should not define the upper bound of an offensive security program.
A motivated adversary has source code, internal documentation, credentials, architecture details, or extensive time to study how the product works. Your security team already has more context than that.
Use it.
Treat source access as part of the threat model, give testers the information advantage available to defenders, and test applications from the perspective of an informed adversary.
Ready to see how Prime continuously tests applications with the same product context an informed attacker would? Learn more at primesec.ai.
Product Security vs Application Security: Key Differences Explained
Your AppSec team closes vulnerabilities faster than ever, but the backlog never shrinks because the same design mistakes keep shipping. That's the gap between application security and product security: AppSec finds implementation bugs after code is written, while product security catches architectural flaws before anyone commits to a bad decision. If fewer than half your known vulnerabilities ever get fixed, the problem isn't remediation speed. It's that you're building things that require heavy remediation in the first place.
What Is Application Security
Application security secures software at the implementation layer: where code lives, where vulnerabilities hide, and where fixes get shipped. AppSec teams find and remediate weaknesses after design decisions have already been made.
The tooling is familiar to most security practitioners:
- SAST (static application security testing) scans source code for known vulnerability patterns
- DAST (runtime application security testing) probes running applications for exploitable flaws
- SCA (software composition analysis) flags risky open-source dependencies
AppSec is reactive by nature, not because AppSec teams aren't sharp, but because the work begins after architectural decisions are locked in. It validates implementation: if a developer writes an insecure authentication flow, AppSec catches it in review. If a third-party library carries a known CVE, SCA surfaces it.
The analogy that lands well internally is building a house. AppSec checks whether the walls are painted according to spec. It does not decide where the fire exits go before construction starts. That's a different job entirely.
TLDR: AppSec secures applications at the code and runtime level using tools like SAST, DAST, and SCA. It operates after design decisions are made, focusing on finding and fixing vulnerabilities in what's already been built.
What Is Product Security
Product security is what happens before anyone writes a line of code. Where AppSec validates what's been built, product security shapes what gets built and how. It's the discipline responsible for embedding security into the product lifecycle from ideation through deployment and end of life.
The scope is broader than any single application. Product security covers:
- Design-stage threat modeling and architecture reviews
- Supply chain risk across third-party components and integrations
- Cross-functional security requirements spanning multiple product surfaces
Most organizations realize this function exists only after they've felt its absence. Only about 10-15% of planned development work typically gets reviewed for security risk, meaning most design decisions ship without security review.
TLDR: Product security embeds security throughout the product lifecycle from design through end of life, covering design reviews, architectural decisions, and supply chain risks well before AppSec's tools come into play.
When Security Enters the Development Lifecycle
TLDR: Product security enters at ideation and design. AppSec enters at development and testing. The earlier security shows up, the cheaper and easier it is to fix what it finds.
Timing is where the two disciplines diverge most sharply. Product security engages at ideation and design, during threat modeling, architecture reviews, and PRD sign-off, before a single line of code is written. AppSec follows later, picking up during development, testing, and pre-release.
That gap matters more than it sounds. A flawed authentication architecture caught at the design stage is a conversation. Caught post-deployment, it's an incident. Research indicates that remediation costs are 6.5x higher during the implementation phase, 15x higher during testing, and 100x higher during maintenance. Product security exists, in part, to capture that savings before anyone commits to a bad decision.

Scope and Coverage Differences
AppSec and ProdSec enter the lifecycle at different times and cover different terrain entirely.
AppSec focuses on individual applications: the code, the runtime environment, the libraries, and the build pipeline. It's a component-level view, thorough within its boundaries, but bounded nonetheless. A vulnerability scanner doesn't care whether the API it's testing exposes data across three product lines or integrates with a third-party payment processor operating under PCI requirements.
ProdSec takes a systems-level view. The questions it asks are broader:
- How do this feature's data flows interact with existing infrastructure?
- What happens when a third-party integration changes its API behavior?
- Does this new component introduce supply chain risk across the entire product?
- Are the cloud services handling this data scoped and configured securely by design?
That difference in scope is why both disciplines can coexist in the same organization without overlap. One secures the parts. The other secures how the parts fit together, and what happens when one of them fails.
| Dimension | Application Security (AppSec) | Product Security (ProdSec) |
|---|---|---|
| When Security Enters | Development, testing, and pre-release phases after design decisions are locked in | Ideation and design phase before any code is written, during threat modeling and architecture reviews |
| Primary Focus | Individual applications at the component level: code, runtime environment, libraries, build pipeline | Systems-level view across entire product ecosystem: hardware, APIs, cloud infrastructure, third-party integrations, compliance |
| Risk Types Each Handles | Implementation bugs: SQL injection, XSS, insecure deserialization, misconfigured headers, vulnerable dependencies | Design flaws and architectural vulnerabilities: broken authentication models, data flows across trust boundaries, systemic supply chain risks |
| Core Tools and Methods | SAST (static analysis), DAST (runtime testing), SCA (composition analysis), vulnerability scanners, code review | Threat modeling, architecture reviews, secure design patterns, frameworks like MITRE ATT&CK, STRIDE, NIST |
| Team Structure | Security engineers embedded with development teams, code reviewers in engineering sprints, vulnerability management specialists | Security architects conducting design reviews, cross-functional liaisons with product/compliance/legal, senior architects for product lines |
| Key Success Metrics | Vulnerability count trends, mean time to remediate (MTTR), test coverage across repositories, CVE backlog reduction | Percentage of work receiving design review, reduction in late-stage rework, compliance audit pass rates, feature time to market |
| Typical Coverage | Scans all code repositories and runtime environments within scope | Only 10-15% of planned development work typically receives manual review due to scale limitations |
| Cost of Fixes | Moderate: bugs found in development are cheaper than production incidents but costlier than design-stage prevention | Lowest when caught early: fixing defects at design stage costs 15x less than fixing them after release |
"AppSec validates implementation; ProdSec defines safe architecture. One is about checking work; the other is about making informed, consequential design decisions."
TLDR: AppSec secures individual apps at the component level. ProdSec covers the full ecosystem: hardware, APIs, cloud infrastructure, third-party integrations, and compliance requirements across the entire product surface.
Team Structure and Responsibilities
AppSec teams live close to engineering. They review pull requests, manage vulnerability scanners, triage findings from SAST and DAST tooling, and work alongside developers to close issues before release. The feedback loop is tight and the work is tactically focused.
Product security teams operate differently, pulling them into conversations with product management, compliance, legal, and even customer success. A product security engineer reviewing a new AI feature is asking whether it meets regulatory requirements, how it affects enterprise trust posture, and what downstream risk looks like if it ships with a flawed data model.
Application Security vs. Product Security Team Roles
Some key structural differences worth noting:
- Application Security: security engineers running SAST, DAST, and SCA tooling, code reviewers embedded in engineering sprints, and vulnerability management specialists tracking CVEs and remediation timelines.
- Product Security: security architects conducting design reviews and threat modeling, a head of product security reporting to the CISO, and cross-functional liaisons working with product, compliance, and customer-facing teams.
Product security functions skew heavier toward senior architects because the work requires judgment beyond tooling. Deciding whether a proposed architecture introduces unacceptable risk is a different skill than running a scanner.
TLDR: Application security teams embed with engineering to test and fix code. Product security teams operate cross-functionally, shaping security frameworks and working across product, compliance, and leadership.
Product Security Engineer Role and Career Path
Product security engineers sit at the intersection of security architecture, risk analysis, and product strategy. Where an application security engineer spends most of their day in code, a product security engineer is more likely to be in a design review, a threat modeling session, or a cross-functional meeting with product and engineering leadership.
The core skill set reflects that breadth:
- Threat modeling and architecture risk analysis
- Secure design patterns and framework knowledge (MITRE ATT&CK, NIST, STRIDE)
- Familiarity with product development lifecycles and agile workflows
- Communication skills to translate risk into business language
Career Progression
Entry-level roles typically start in application security or general security engineering. Practitioners who develop a taste for upstream, design-stage work tend to migrate toward product security over time. Senior roles lean heavily on security architecture experience, and the most senior individual contributors often function as de facto security architects for entire product lines.
TLDR: Product security engineers bridge security architecture and product strategy, requiring threat modeling skills, design-stage judgment, and cross-functional communication.
Risk Types Each Discipline Handles
The risks each discipline catches are as different as the phases they work in.
AppSec handles implementation-layer problems: SQL injection, cross-site scripting, insecure deserialization, misconfigured headers, and vulnerable dependencies. These are bugs introduced during development, catchable with scanners and code review.
Product security handles a different category entirely:
- Design flaws: an authentication model that's fundamentally broken before a single function is written
- Architectural vulnerabilities: data flows that expose sensitive information across trust boundaries by design
- Systemic risks: supply chain dependencies or third-party integrations that introduce risk at the ecosystem level
The distinction matters because design flaws can't be patched out. If an architecture routes unencrypted PII through an unsecured internal service, no SAST tool fixes that. It gets rebuilt or it ships broken.
TLDR: AppSec catches bugs and misconfigurations in code. Product security catches flawed designs, risky architectures, and systemic vulnerabilities before implementation makes them permanent.
How Product Security and Application Security Work Together
Neither discipline wins without the other. AppSec finds what slipped through. Product security tries to prevent it from slipping through in the first place. Organizations that treat them as competing priorities end up with gaps in both directions.
The handoff looks like this: product security defines the security requirements and architectural constraints before development begins. AppSec then validates that those requirements were actually implemented correctly. When coordinated, a flaw caught by SAST can inform the next design review. When siloed, the same class of vulnerability ships repeatedly because no one connected the pattern upstream.
Mature teams formalize this through shared frameworks and joint governance:
- Unified SDLC checkpoints where both functions sign off at different stages
- Shared vulnerability data that feeds back into design-stage decisions
- Cross-functional design reviews where AppSec input informs architectural choices
TLDR: Product security and AppSec cover different layers and work best when coordinated. Product security sets the design requirements; AppSec validates their execution. Together, they close the loop between intent and implementation.
Measuring Effectiveness and Success Metrics
AppSec and product security don't share KPIs because they don't share problems. Measuring one with the other's metrics tells you almost nothing useful.
AppSec success looks like:
- Vulnerability count trends over time
- Mean time to remediate (MTTR)
- Test coverage across code repositories
- CVE backlog reduction
Product security success looks different:
- Percentage of planned development work that received a design review
- Reduction in design rework caused by late-stage security findings
- Compliance audit pass rates and audit readiness posture
- Time to market for new features that cleared secure-design requirements
The coverage metric is worth sitting with. If only 10-15% of planned work gets reviewed, a product security team with zero vulnerabilities in queue isn't success. They're just not looking. Coverage is the floor everything else stands on.
What those metrics signal, together, is whether security is integrated or reactive. AppSec numbers tell you how well the organization remediates. Product security numbers tell you whether the organization is building things that need heavy remediation in the first place.
TLDR: AppSec measures vulnerability counts, MTTR, and test coverage. Product security measures design review coverage, compliance posture, and reduced rework. Each set reflects a different layer of organizational security health.
Common Challenges and Limitations
Both disciplines are harder to run well than org charts suggest.
AppSec teams deal with tool sprawl, scanner noise, and developer friction. The more tools you add, the more alerts pile up, and the less any single finding gets taken seriously. Alert fatigue is a genuine triage failure that lets real vulnerabilities age out in a backlog.
Product security faces a different wall: scale. Manual threat modeling depends on a handful of senior engineers who can't be in every design review. The result is that only 10-15% of planned work actually gets reviewed, and the other 85-90% ships without structured security input.
What makes both problems worse is the perception gap. While 81% of organizations say their security posture is strong, fewer than 48% of known vulnerabilities ever get remediated, according to Tenable. Confidence outruns execution by a wide margin.
TLDR: AppSec struggles with alert fatigue and tool overload. Product security struggles with coverage and scale. Together, they explain why 81% of orgs feel secure while fewer than half of vulnerabilities are actually closed.
How AI-Powered Development Is Changing the SDLC
AI agents are reshaping software architecture faster than any security review process was designed to handle. Where a sprint once moved at human pace, AI-assisted development compresses weeks of work into hours. The security functions built around that older cadence, weekly design reviews, manual code audits, quarterly threat model refreshes, were not designed for this velocity.
The result is not just more work. It is a fundamentally different risk profile. AI-generated code is expanding the attack surface faster than teams can scan it, compliance assumptions made last quarter are already stale, and the design decisions that product security exists to catch are now arriving in volume that manual review cannot absorb. Both disciplines feel this pressure, but in different ways.
What AI-Powered Development Means for AppSec
AI-generated code looks clean. It passes linters, follows style guides, and ships fast. It can also introduce subtle vulnerabilities that pattern-matching scanners miss, because the patterns themselves are new. AppSec teams are watching CVE backlogs grow faster than they can close tickets, not because remediation slowed down, but because the code surface is expanding at a pace manual review was never built to match.
- Developers using AI coding assistants do not always signal what changed or why. Pull request descriptions get thinner, commit messages reference the prompt rather than the intent, and the context AppSec needs to prioritize findings is harder to reconstruct after the fact.
- AI-generated code can produce vulnerability classes that trained scanners have limited coverage for, because the patterns are novel or the context is stripped away.
- Alert fatigue, already a structural problem, compounds when code volume and findings scale nonlinearly while security headcount stays flat.
The throughput problem AppSec already faced gets harder when the denominator keeps growing. Teams that were stretched at a 50:1 developer-to-security ratio are now effectively operating at much higher ratios, without any change to the org chart.
What AI-Powered Development Means for Product Security
For product security, the challenge is architectural. AI agents do not just write functions. They propose integrations, suggest third-party services, and draft entire system designs. When a developer accepts a suggestion that routes sensitive data through an external API, that is an architectural decision made without a design review. Multiply that by every developer on every team, every day, and the 10-15% design review coverage problem gets harder to close, not easier.
- Threat models written last quarter may already be stale. Architectures shift between standups when AI is accelerating feature development.
- Third-party integrations and cloud service configurations, the supply chain risks product security is responsible for evaluating, are being introduced faster than any manual review process tracks.
- The design-stage conversation that product security exists to have is increasingly happening between a developer and an AI assistant, with no security input in the room.
The 85-90% of planned work that does not receive a design review was already a coverage problem. AI-assisted development does not improve that number. It raises the stakes attached to each missed review.
TLDR: AI-powered development accelerates the exact risks both AppSec and ProdSec were built to address. AppSec teams face higher code volume, thinner commit context, and growing backlogs. Product security teams face architectural decisions happening faster than design reviews can follow, with threat models going stale before the ink is dry.
When to Invest in Product Security Versus Application Security
AppSec is the baseline. Any organization shipping software needs it. Product security becomes the priority when your products grow complex enough that architecture decisions carry real downstream risk.
A few signals that product security investment is overdue:
- Design rework is eating sprint capacity because security catches issues too late
- Enterprise customers or regulators are asking about your secure development practices
- Your developer-to-security ratio has crossed 50:1 and reviews are not keeping pace
- You're shipping AI features or third-party integrations with no formal design review process
Early-stage companies typically start with AppSec, add a product security function around Series B or C, and formalize it once regulatory pressure or customer scrutiny makes informal processes unsustainable.
TLDR: AppSec first, always. Add product security when product complexity, compliance requirements, or enterprise trust expectations outgrow what reactive tooling can cover.
How Prime Security Automates Product Security at Scale
The scaling challenges outlined throughout this post aren't unsolvable. They're just unsolvable with manual processes.
Prime continuously scans Jira, Confluence, and connected planning tools to surface design-stage risks across all planned development work, not the 10-15% that fits into a security team's calendar. Acting as an Agentic Security Architect, Prime automates design reviews, threat modeling, and risk analysis, so coverage expands without adding headcount.
That continuous coverage matters most when AI-assisted development is accelerating the pace of architectural decisions. When developers are accepting AI-suggested integrations, routing data through new third-party APIs, and drafting system designs faster than any manual review cadence was built to handle, the 85-90% design review gap gets harder to close without automation. Prime keeps pace with that velocity by scanning planning artifacts as they are created and updated, not on a weekly or quarterly review schedule. Threat models stay current because Prime is continuously re-evaluating them, not waiting for a senior engineer to have a free afternoon.
The output is consistent, auditable, and architect-level in reasoning. Reviews that previously took days run in under 20 minutes. Findings land directly in engineering workflows, not in a spreadsheet no one checks.
If your team is the bottleneck between design and deployment, that's worth fixing before the next release cycle.
TLDR: Prime automates product security design reviews at scale, expanding coverage from 10-15% to nearly 100% of planned work by integrating directly into Jira and Confluence. That continuous scanning is especially critical when AI-assisted development is compressing weeks of architectural decisions into hours, without slowing engineering down.
Final Thoughts on Product Security Versus Application Security
Understanding product security versus application security changes how you allocate your security resources and where you intervene in the development lifecycle. AppSec finds the bugs, but product security stops entire classes of vulnerabilities from becoming architecturally possible. If fewer than half your known vulnerabilities get remediated and only 10-15% of planned work receives design review, you're solving the wrong bottleneck. Prime brings architect-level design reviews to every Jira ticket, every PRD, and every planned feature before engineering writes a line of code.
FAQ
Product security vs application security: what's the actual difference?
Product security shapes design decisions before code is written, while application security validates the code itself. Product security asks "where do the fire exits go?" during architectural planning; AppSec checks whether the walls were built to spec after construction starts.
What skills do you need to become a product security engineer?
You need threat modeling and architecture risk analysis skills, familiarity with frameworks like MITRE ATT&CK and STRIDE, understanding of product development lifecycles, and the ability to translate security risk into business language. Most product security engineers start in AppSec roles and move upstream once they develop design-stage judgment.
Can product security reviews actually keep up with AI-assisted development?
Manual reviews can't, which is why most organizations only review 10-15% of planned work. AI-powered platforms can continuously scan development plans and automate design reviews, expanding coverage to nearly 100% without adding headcount or slowing engineering velocity.
When should a company invest in product security versus just doing AppSec?
Invest when design rework is eating sprint capacity because security catches issues too late, when your developer-to-security ratio exceeds 50:1, or when enterprise customers start asking about your secure development practices. AppSec is the baseline; product security becomes critical when architectural decisions carry real downstream risk.
Build vs Buy: Automating Security Design Reviews at Scale
The Decision You're Actually Making
Most security teams can build an AI-assisted security review workflow. The question is whether you want to own what it takes to make that system production-grade, accurate, and maintainable, indefinitely. That's a different question, and the answer changes the math significantly.
What Is Prime Security?
Prime Security is a purpose-built AI security review platform designed for software development lifecycles (SDLCs). Unlike generic AI tools or in-house workflows, Prime uses a persistent context graph, a structured knowledge layer that connects your architecture, trust boundaries, business logic, internal controls, and historical security decisions. This means security reviews grow more accurate over time rather than starting from scratch with each request.
Prime covers the full development lifecycle: architecture reviews, threat modeling, documentation analysis, and security analysis tied to tickets and code changes. Agents run continuously across planning and development workflows without requiring custom engineering from your team.
What Does Building In-House Actually Cost?
Early-stage AI security tooling is fast to prototype and hard to scale. Security teams that have gone down this road consistently hit the same wall:
1. Context degrades at scale
Useful security analysis requires understanding your architecture, trust boundaries, historical decisions, and internal controls, not just the ticket in front of the model. Systems that reconstruct this context per request become inconsistent as the codebase and team grow. There is no compounding institutional knowledge; every review starts from near zero.
2. Agentic operation becomes a platform engineering problem
Triggering a review on demand is a demo. Running continuous, autonomous reviews across planning, documentation, and development workflows, with retries, orchestration, and write-back into engineer tooling, is a significant ongoing engineering commitment that compounds as your stack evolves.
3. You end up owning a second product
Maintaining a home-grown AI security system means owning the prompts, the evaluation framework, the integrations, and the improvement cycle. Security expertise encoded in prompts drifts as your architecture changes. Without a dedicated team to run that loop, accuracy degrades quietly, often without anyone noticing until a review misses something it shouldn't.
The build path isn't wrong. For experimentation or limited scope, it can be the right call. But for SDLC-wide Product Security coverage, teams that build often find they've created a second product to maintain.
When Does Building Make Sense?
Building in-house is a reasonable choice when:
- You are running a limited-scope proof of concept or internal experiment
- Your security review surface is narrow and stable (e.g., one team, one repo)
- You have dedicated ML/security engineering bandwidth to own and iterate on the system long-term
- You are not yet ready to evaluate external vendors
For any of the following, the buy path will typically cost less over 12–18 months: SDLC-wide coverage, multiple engineering teams, frequent architectural change, or a security team without dedicated tooling engineers.
What Prime Does Differently
Prime is purpose-built for the part that's hard to build: persistent, context-aware security reasoning across the entire development lifecycle.
Prime's core advantage isn't automation. It's that Prime's persistent context graph connects architecture, business logic, and historical security decisions, so reviews stay accurate as your systems and team evolve, without ongoing engineering investment to keep them that way.
How Prime Compares to Home-Grown Solutions
| Dimension | Home Grown Solutions | Prime Security |
|---|---|---|
| Context understanding | Reconstructed on request; typically limited to documents passed to the model or basic retrieval layers | Persistent context graph connecting architecture; assets; controls; policies; and historical decisions |
| Accuracy | Degrades as system grows and architectural context becomes harder to reconstruct | Improves over time as context accumulates grounded in architecture; business logic; and historical decisions |
| Deployment | Requires custom orchestration, triggers, monitoring, retries, and integration with engineering workflows | Agents operate continuously across planning systems, documentation, and development workflows |
| Security knowledge | Expertise encoded in prompts or scattered documentation; drifts as the system changes | Institutional security reasoning layer capturing organizational knowledge and past decisions |
| Longevity | Requires ongoing internal engineering effort to maintain prompts, workflows, integrations, and evaluation frameworks | Vendor-managed platform with continuous improvements in reasoning accuracy and workflow integration |
How Prime Is Different from SAST or Traditional AppSec Tools
Prime Security focuses on security design review and threat modeling across the SDLC, not static code scanning. It applies contextual reasoning grounded in your architecture, business logic, and past security decisions, producing reviews that account for how your system actually works rather than flagging generic code patterns.
Traditional SAST tools catch known vulnerability patterns in code. Prime catches architectural and design-level risks before they reach code, and integrates that context with the decisions your team has already made.
Result: What Teams See After Deploying Prime
“A s our development velocity increased, especially with A I, we needed a force multiplier we could actually trust. Prime gives us consistent, high-quality security reviews and threat models across our entire surface area, and the confidence to operate at speed ."
A l Faiella, Sr . Director of Product Security
Thoughtspot
ThoughtSpot outcomes after deploying Prime:
- 5x increase in security reviews capacity
- 30-minute reduction in per-review execution time
- 100% coverage accross all development surface area
The Bottom Line
You can build a prototype. Prime gives you a system.
If your goal is scalable Product Security review coverage. not a prototype, but a system your team can rely on, the build path will cost more in engineering time and security accuracy than it first appears.
Prime gets you to production-grade coverage faster, with a reasoning layer that improves over time rather than one you have to rebuild every time your stack changes.
Frequently Asked Questions
Should I build an AI security review tool in-house or buy a solution like Prime?
Short answer: Buy, unless you are experimenting at limited scope. For SDLC-wide Product Security coverage, a purpose-built solution is faster to deploy and lower-cost to operate than building in-house. Teams that build often end up owning a second product, with ongoing investment in prompts, orchestration, and integrations, and no built-in mechanism for improving accuracy over time.
What is Prime Security's core advantage over home-grown solutions?
Prime uses a persistent context graph that connects architecture, business logic, controls, and historical security decisions, so reviews stay accurate as your systems and team grow, without requiring internal engineering effort to maintain them. The key distinction is that Prime's accuracy improves over time; home-grown systems tend to degrade.
How much does Prime Security reduce review time?
Prime delivers 5x review capacity, reduces review execution time by 30 minutes per review, and provides 100% coverage across all development surface area, based on results reported by ThoughtSpot.
What is a persistent context graph in AI security reviews?
A persistent context graph is a structured knowledge layer that connects your architecture, trust boundaries, business logic, controls, and historical security decisions. In security reviews, it means the system builds on prior decisions instead of reconstructing context from scratch with each request, so review accuracy improves as your codebase and team grow.
What development workflows does Prime Security cover?
Prime Security covers the full software development lifecycle: architecture reviews, threat modeling, documentation analysis, and security analysis tied to tickets and code changes. Agents run continuously across planning systems and development workflows without requiring custom orchestration from your engineering team.
How is Prime Security different from a SAST or traditional AppSec tool?
Prime Security focuses on security design review and threat modeling across the SDLC, not static code scanning. It applies contextual reasoning grounded in your architecture, business logic, and past security decisions, producing reviews that account for how your system actually works rather than flagging generic code patterns.
What are the signs that a home-grown AI security tool is failing?
Common failure signals include: review quality becoming inconsistent as the codebase grows, reviewers having to re-explain the same architectural context in every session, increasing engineering time spent on prompt maintenance and integration upkeep, and security reviews missing issues that depend on historical architectural decisions. If your team is spending more time maintaining the tool than using it, that's a strong indicator.
How long does it take to deploy Prime Security?
Because Prime is vendor-managed and purpose-built for SDLC security workflows, deployment does not require building orchestration, writing evaluation frameworks, or standing up custom integrations from scratch. Teams can reach production-grade coverage significantly faster than the build path, which typically requires months of engineering investment before reviews are consistently reliable.
Is Prime Security suitable for fast-growing engineering teams?
Yes. Prime is specifically designed for environments where development velocity is increasing and the security team cannot linearly scale headcount to match. The persistent context graph ensures review quality stays consistent even as the number of engineers, repos, and architectural decisions grows.
Does Prime Security replace human security engineers?
No. Prime functions as a force multiplier for your existing security team, handling continuous coverage, routine reviews, and surface area that would otherwise require manual triage. Security engineers are freed to focus on higher-judgment work: novel threat patterns, architectural decisions, and cross-functional security strategy.
Ready to see it in your environment?
We'll scope a POC around your stack and team size - or set up a peer reference call with a security leader who's been through this decision.
How to Conduct a Security Design Review: April 2026
When you run a security design review manually, you spend half your time hunting down context that should have been included upfront. Half-written Jira tickets, outdated architecture diagrams, Slack threads explaining what the PRD didn't: this is what passes for documentation. Understanding security design reviews means knowing what questions to ask and which frameworks to apply, but it also means accepting that each review will consume hours reconstructing information before you can analyze actual risk. Your coverage stays stuck at 10 to 15 percent because the overhead never scales down.
What a Security Design Review Is and Why It Matters
A security design review happens before code gets written. Security teams analyze planned features, architectures, and system changes to identify risks while they're still theoretical. The goal is to shape what gets built, instead of inspecting it after the fact.
This matters because of basic economics. Fixing security flaws costs 100x more when found late in development. Refactoring a live system beats rewriting a paragraph in a document every time.
Design reviews differ from tools like SAST and DAST, which scan existing code. Those tools are valuable but reactive. Design reviews operate upstream, deciding where the fire exits go instead of checking if the paint meets spec.
When to Trigger a Security Design Review
Knowing when to trigger a review is half the problem. Most organizations rely on developers self-reporting or informal Slack requests. The result: only high-visibility projects get reviewed, while risky changes slip through because no one knew to ask.
Clear trigger criteria solve this. Reviews should automatically start when development work involves:
- New authentication or authorization mechanisms
- Third-party integrations that handle customer data
- Changes to API endpoints that expose sensitive resources
- Infrastructure changes affecting network segmentation
- Processing of compliance-controlled data types (PII, PHI, payment card data)
- New data stores or major schema changes
- AI model integrations or code generation workflows
Requesting and Scoping the Review: What Security Teams Need
Once a review gets triggered, security needs complete context to work effectively. In theory, teams submit complete PRDs, architecture diagrams, and data flow maps. In practice, you're handed a half-written Jira ticket and a Slack thread.
The gap between what you need and what you get defines the friction. Security teams spend hours hunting down information that should have been included upfront. You're looking for:
- Product requirements document explaining the feature's purpose, user flows, and business logic
- Technical design spec covering system components, data models, and integration points
- Architecture diagrams showing how services communicate and where data lives
- Data classification details identifying what sensitive information gets processed
- Existing security controls relevant to the affected systems
- Compliance requirements that apply to the planned changes
- Dependencies on third-party services or libraries
You won't get all of this upfront. The question is whether you spend your time reconstructing missing context or analyzing actual risk. That difference determines whether reviews take 30 minutes or three days.
Data Flow Analysis and Trust Boundaries
Data flow analysis maps where information travels and how it changes across system boundaries. Track every input, processing step, and output to understand what happens as data moves through your architecture.
Start by identifying entry points where data enters the system: user forms, API calls, file uploads, and third-party webhooks. Then trace the path through each service, transformation, and storage point.
Trust boundaries mark where security assumptions change. Data moving from a user's browser to your API crosses one. So does information flowing from your application to a third-party payment processor. Each boundary changes validation, authentication, and encryption requirements.
Document what data types cross each boundary, which security controls protect them, and where assumptions about integrity or confidentiality change. A diagram showing "User → API → Database" reveals nothing about PII encryption or access control differences between layers.
Threat Modeling Frameworks: STRIDE, MITRE ATT&CK, and LINDDUN
Threat modeling frameworks give security teams a structured way to ask "what could go wrong?" They're thinking tools, not checklists, helping you systematically surface risks that informal analysis misses.
STRIDE categorizes threats by type: Spoofing, Tampering, Repudiation, Information Disclosure, Denial of Service, and Elevation of Privilege. Use it when reviewing application features and data flows.
MITRE ATT&CK maps real-world attacker techniques based on observed breaches. It's best for infrastructure changes, third-party integrations, and scenarios requiring reasoning about how adversaries actually operate.
LINDDUN focuses on privacy threats: Linkability, Identifiability, Non-repudiation, Detectability, Disclosure of Information, Unawareness, and Non-compliance. Apply it when processing personal data or building features subject to GDPR, CCPA, or HIPAA.
Most security teams struggle to apply these frameworks consistently.
| Framework | Primary Focus | Best Used For | Key Threat Categories | Typical Review Time |
|---|---|---|---|---|
| STRIDE | Application and system-level security threats | Feature development, API design, authentication flows, and data processing workflows | Spoofing, Tampering, Repudiation, Information Disclosure, Denial of Service, Elevation of Privilege | 1-2 hours for standard features; 3-4 hours for complex architectures |
| MITRE ATT&CK | Real-world adversary tactics and techniques | Infrastructure changes, cloud migrations, third-party integrations, and incident response planning | Mapped to actual attack patterns including initial access, persistence, privilege escalation, lateral movement, and exfiltration | 2-3 hours; requires understanding of adversary behavior and attack chains |
| LINDDUN | Privacy threats and compliance risks | Features processing personal data, GDPR/CCPA compliance reviews, user profiling systems, and data retention policies | Linkability, Identifiability, Non-repudiation, Detectability, Disclosure of Information, Unawareness, Non-compliance | 1-3 hours depending on data sensitivity and regulatory requirements |
| OWASP ASVS | Application security verification standards | Web applications, mobile apps, API security validation, and building security requirements baselines | Structured checklist covering authentication, session management, access control, input validation, cryptography, error handling, and logging | 2-4 hours for complete coverage; can be used incrementally for specific security domains |
Risk Analysis and Prioritization
Risk analysis ranks threats by balancing exploitation likelihood against business impact. CVSS scores miss critical context. A severe vulnerability in a three-person admin tool differs from a moderate flaw in customer payments, which affects revenue and compliance.
Use a simple matrix pairing likelihood (low, medium, high) with impact (low, medium, high), then layer in business judgment. What breaks if this threat succeeds? Customer data exposure, service interruption, and regulatory violations all carry different weight. A low-likelihood, high-impact risk in your revenue system typically beats a medium-likelihood, low-impact issue in a logging service.
Context beats formulas. Teams that rank risks against real operations get fixes shipped.
Developing Specific and Actionable Recommendations
Generic recommendations waste everyone's time. "Implement proper input validation" tells developers nothing. Which inputs? What validation? Using which library?
Actionable recommendations specify what to do and how. Instead of "encrypt sensitive data," write "encrypt customer PII fields using AES-256-GCM via the existing CryptoService wrapper before writing to the customer_data table." Reference actual classes, endpoints, or services the team already uses.
Distinguish between blocking issues and improvements. Blocking findings prevent launch: unauthenticated admin endpoints, SQL injection in payment flows, exposed credentials. Recommended improvements strengthen security posture without being critical path: rate limiting on public APIs or shorter-lived token rotation.
Clarity on severity helps engineering sequence work without endless negotiation.
Communicating Findings into Developer Workflows
Findings in Jira get fixed. Developers work in specific tools, and context-switching kills follow-through.
Create tickets linked to the relevant epic or story, with findings as subtasks. For code-level issues, open GitHub issues or PR comments tied to files. Document decisions somewhere permanent. Slack threads disappear.
Match format to severity. Critical issues need synchronous discussion: a 15-minute call beats three days of async threading. Medium-severity findings fit ticket descriptions with acceptance criteria. Low-priority items batch into a single issue reviewed during sprint planning.
Meet engineering in their existing tools to see faster remediation.
Validating That Mitigations Were Implemented
Recommendations get documented, tickets get closed, and teams assume the work is done. Validation proves whether mitigations actually shipped or just got marked complete.
Manual follow-up works at small scale: schedule a 30-minute review where security spot-checks implemented changes against original recommendations. Code review catches tactical fixes, confirming that encryption calls use the right algorithms or authentication checks happen before data access.
Automated validation closes the loop permanently. Write tests that fail if mitigations regress: integration tests verifying auth requirements, security scanning rules that flag missing encryption, or CI/CD gates that block deploys when recommended controls are absent.
Why Manual Security Design Reviews Cannot Scale
Manual design reviews consume 2-4 hours of senior security engineer time per feature. Engineering ships dozens each sprint. The math doesn't work.
Most organizations review 10 to 15 percent of planned work. The rest ships without analysis because teams can't scale. Even at a healthy security-to-developer ratio of 1:100, covering every design means each security engineer spends 20-30 hours weekly just on reviews.
Common workarounds fail. Generic checklists miss context-specific risks. Delegating to junior staff produces inconsistent outputs. Developer self-assessments create false confidence without catching real threats.
AI-assisted development widens the gap. Code generation tools let engineering ship faster while manual review speed stays constant.
Human expertise won't scale to match. Coverage drops and risks accumulate across the backlog.
How Prime Security Automates Security Design Reviews
Prime acts as an AI Security Architect that runs continuously alongside engineering. The system scans Jira, Confluence, and planning tools to identify design-stage risks across all planned work, expanding coverage from 10 to 15 percent to nearly 100 percent.
Prime aggregates context automatically, interprets requirements, applies STRIDE and MITRE ATT&CK, and generates mitigation recommendations in under 20 minutes. Findings flow directly into developer workflows as Jira tickets or GitHub issues.
The system builds institutional memory as you conduct reviews. Past decisions, design patterns, and risk tolerance preferences inform future analysis, creating consistency without requiring the same senior engineer on every review.
Final Thoughts on the Security Design Review Processes
Your security team probably reviews a fraction of planned work not because you're bad at prioritization but because the process itself can't scale. Security design reviews done manually consume more time than most organizations have available, leaving risky changes to ship without analysis. The core problem isn't methodology or frameworks, it's that human-driven review speed stays constant while development velocity keeps increasing. Automation handles the repetitive parts like context gathering and threat enumeration so your architects focus on judgment calls that actually need human expertise. See what automated reviews look like in your environment.
FAQ
How long does a security design review typically take?
Manual reviews consume 2-4 hours of senior security engineer time per feature, while Prime's automated approach completes the same analysis in under 20 minutes by automatically aggregating context and applying threat modeling frameworks.
What's the difference between a security design review and tools like SAST or DAST?
Design reviews happen before code gets written and shape what gets built, analyzing planned features and architectures to identify risks while they're theoretical. SAST and DAST scan existing code after it's written, making them reactive instead of preventive.
When should I trigger a security review for a new feature?
Trigger reviews when development involves new authentication mechanisms, third-party integrations handling customer data, API endpoint changes exposing sensitive resources, infrastructure modifications affecting network segmentation, processing of compliance-controlled data types, new data stores, or AI model integrations.
Why can't manual security design reviews scale with modern development?
At a healthy 1:100 security-to-developer ratio, covering every design means each security engineer spends 20-30 hours weekly just on reviews. Most organizations review only 10-15% of planned work because the math breaks down when engineering ships dozens of features each sprint.
Can I validate that security mitigations were actually implemented?
Yes, through manual spot-checks where security reviews compare implemented changes against original recommendations, or through automated validation like integration tests verifying auth requirements, security scanning rules flagging missing encryption, or CI/CD gates blocking deploys when recommended controls are absent. You can also link a GitHub repository or pull request directly to a mitigation, allowing you to formally identify and confirm whether a specific control has been implemented. This provides a clear, traceable audit trail from recommendation to resolution.
Context is King: Finding Vulnerabilities Was Never the Hard Part
On Feb 19th, 2026, the cyber earth shook! The cyber security market lost billions in a single afternoon. JFrog dropped 25%. CrowdStrike fell 8%. And all because Anthropic launched Claude Code Security.
Here’s what I find fascinating: the market panicked about the wrong thing.
Claude Code Security is genuinely impressive, an AI model that reasons about code like a security researcher, finds zero-days that survived decades of expert review, and suggests patches for human approval. That’s a HUGE milestone. But the breathless headlines about AI “replacing” cybersecurity miss a fundamental truth:
Finding vulnerabilities has never been the hard part. Knowing what to do about them is.
Better scanners don’t solve the real problem
What Anthropic built matters. Reasoning-based vulnerability discovery is a genuine leap, and static analysis becoming embedded in AI coding platforms is the right direction for the industry.
But enterprise security teams aren’t starved for findings, they’re drowning in them. SAST, DAST, SCA, container scanners, each one generating alerts, none capable of answering the only question that matters:
“Should I care about this one?”
That’s a context question. And it eats 80% of a security team’s time.
Claude Code Security is a dramatically better way to find code-level vulnerabilities. But it doesn’t know your architecture, your compliance obligations, or the security exceptions your architect approved last quarter. Without that context, even the most brilliant finding is just another alert in the queue.
Same vulnerability, two completely different realities
Let me make this concrete. Imagine Claude Code Security finds an insecure direct object reference (IDOR) in your codebase. A user can manipulate an API parameter to access another user’s data. The scanner flags it as high severity and even suggests a patch. Impressive work.
Now what?
Without business context, your security team sees one more high-severity finding in a backlog of 200. An engineer spends 45 minutes triaging; pulling up architecture diagrams, pinging the team lead on Slack, digging through Confluence. They eventually discover it’s an internal admin tool used by six people, accessible only through a VPN behind SSO. The IDOR is real, but the blast radius is tiny. Forty-five minutes gone. Multiply that by 30 findings a day.
That’s not security engineering. That’s archaeology.
With organizational context, the same IDOR gets instantly enriched by Prime’s Security Context Engine: Checkout Service, Tier 1, internet-facing, PCI-DSS. The design review eight weeks ago recommended object-level authorization checks and was linked to a Jira ticket which was deprioritized after a production incident. The feature team ships in six days.
Same vulnerability. First scenario: 45 minutes to figure out whether to care. Second: the team acts within seconds due to a critical finding, compliance obligation, known fix, tight deadline.
That’s the difference context makes. A fundamentally different operating model.
This is exactly why we built Prime
Prime’s Security Context Engine is an organizational context graph. A living map of your security architecture decisions, risk exceptions, and compliance requirements. The institutional memory that turns raw findings into actionable intelligence.
Any scanner can tell you what’s wrong. Prime tells you why it matters to your organization, and what to do about it.
Detection is maturing. Context is just getting started.
The Claude Code Security launch validates the thesis we’ve been building around since day one.
Scanning and operationalization tools play a vital role in any mature security program. But detection is converging fast. When a frontier AI model can discover 500 zero-days with no custom scaffolding, the race to find more bugs has a ceiling.
What doesn’t have a ceiling is organizational knowledge. That knowledge compounds with every design decision processed, every review completed, every exception documented. It deepens with time, and new entrants can’t shortcut it.
The three-layer future of product security
Here’s how I see the product security stack evolving:
Layer 1: Design-stage intelligence. Before code is written, understand the security implications of what you’re about to build. This is Prime’s core, automated security and privacy design reviews with architect-level guidance in real time.
Layer 2: Code-level scanning. Once code is written, scan it for vulnerabilities. Claude Code Security, traditional SAST/DAST tools, SCA analyzers live here. This layer is getting dramatically better and cheaper.
Layer 3: Runtime protection and response. Endpoint detection, identity management, network security. CrowdStrike, Cloudflare, Okta and the likes were never threatened by a code scanner, and the market selloff was, as Barclays put it, “illogical.”
The insight is that Layer 1 makes Layer 2 dramatically more useful. When you understand your architecture and design decisions before code is written, every finding from a scanner arrives pre-contextualized. You’re not triaging from scratch, you’re confirming or updating what you already know.
And the benefits to layer 3 I’ll leave to a separate post…
The question security leaders should actually be asking
Anthropic’s Claude Code Security is a genuinely exciting development for defenders. But better scanners mean more findings. More findings without context means more noise. And the real question this launch should prompt isn’t “will AI replace my security tools?” it’s “am I positioned to absorb the coming flood of AI-generated findings?”
The organizations that thrive won’t be the ones with the best scanners, they’ll be the ones that can instantly contextualize any finding against their specific risk posture and act on what actually matters.
Scanners find. Context decides.
And context is king.
We Benchmarked AI Models on Architecture Diagrams at Scale
In the age of AI-driven development, architecture matters more than ever. Prompts don't change individual lines of code, they change how systems are composed, connected, and allowed to interact. But to change an architecture, you first need to understand what already exists.
In most organizations, that understanding lives in architecture diagrams across tools like Lucid, Draw.io, Miro, and other diagramming platforms.
We benchmarked leading AI models on their ability to understand these diagrams at scale and found that while general-purpose models work on small systems, they break down quickly as complexity grows. Prime maintained accurate system-level understanding even on large, complex architectures, highlighting the difference between describing diagrams and reasoning about real systems.
Why does architecture understanding matter for AI-driven development?
As software systems grow more distributed, interconnected, and automated, architecture has become the primary unit of change. Products are no longer shaped line by line, but by decisions about composition, interaction, and boundaries.
The core decisions that manifest in architecture include:
- How services are composed
- Where trust and responsibility boundaries exist
- Which components are allowed to communicate by default
- How data flows across the system
Once AI enters the development loop, many of these decisions stop being explicit. Choices about service boundaries, dependencies, and integration patterns are increasingly embedded inside prompts and generated artifacts, rather than surfaced through formal design discussions. In practice, the most durable record of those decisions lives in architecture diagrams across tools like Lucid, Draw.io, Miro, PowerPoint, and similar systems-diagrams that reflect how teams actually reason about structure, dependencies, and boundaries.
That leads to a very practical question: If AI systems are going to contribute to building modern software, can they reliably understand the architectures organizations already use to reason about change?
Where architecture diagram understanding breaks down
In practice, this is where teams start to run into problems.
Through our work at Prime with Security Architecture and Product Security teams, we repeatedly saw the same pattern. Uploading an architecture diagram into an LLM often appears to work at first. The model describes the system, names key components, and even infers a few flows.
But as diagrams grow in size or complexity, exactly where real production systems live, the output becomes unreliable:
- Components are missed or merged
- Relationships are dropped or misrepresented
- Trust boundaries disappear
- Critical structure is confidently simplified away
This wasn't a prompt issue, and it wasn't tied to any single model. We saw the same failure modes across teams, tools, and use cases. What broke wasn't the explanation, it was the model's ability to preserve system structure as complexity increased.
At that point, the question stopped being "can LLMs describe diagrams?" and became something more fundamental.
So we decided to measure it.
The experiment: How well can AI models understand architecture diagrams?
We designed a benchmark to test how well different AI systems can understand and extract structure from architecture diagrams.
Systems tested
We ran the experiment across multiple leading, state-of-the-art models, alongside improved methodologies we developed at Prime, using the same inputs and prompts.
What we measured
Two core capabilities:
Node accuracy – How accurately the model identifies and classifies components in the diagram
Edge accuracy – How accurately the model identifies relationships, flows, and connections between components
Edges are particularly important from a security perspective, since they represent data flows, trust boundaries, and potential attack paths.
Methodology
- We used architecture diagrams at increasing levels of complexity, ranging from small diagrams (~15 nodes) to large diagrams (~150 nodes and ~160 edges)
- Each test was run three times per model, averaging the results
- Inputs were high-resolution PNG images generated using draw.io
- Prompts were kept consistent across runs to eliminate prompt bias
- The same diagrams and prompts were used for all models
Can AI models accurately extract components from architecture diagrams?
Node accuracy results

All models performed well on small diagrams. The problems appeared quickly as scale increased:
- Once diagrams exceeded roughly 30-40 nodes, general-purpose models began to degrade rapidly
- Accuracy collapsed entirely for some models by ~50 nodes
- Prime maintained ~95–100% accuracy even at 150+ nodes
The degradation wasn't gradual decline, it was structural collapse. Models that correctly identified 95% of components in a 20-node diagram would miss or merge half the components in a 60-node system.
Can AI models accurately identify relationships in complex architectures?
Edge accuracy results

Edge extraction proved significantly harder for every system, and this is where the real problem lives.
- General-purpose models showed steep degradation as edge count increased
- Some dropped to near-zero accuracy well before 100 edges
- Prime stabilized at consistent accuracy even at the highest complexity tested
This distinction matters: identifying components is useful, but understanding how those components interact is where security insight actually comes from. A model that can list every service in your architecture but cannot reliably map which services communicate, where data flows, or which boundaries matter is fundamentally unable to support threat modeling or design review at scale.
The gap between "can describe a diagram" and "can model a system" becomes obvious once relationships enter the picture.
What causes AI models to fail at architecture diagram understanding?
This experiment highlights a fundamental difference in how AI systems reason about architecture.
General-purpose LLMs treat diagrams primarily as visual artifacts. They interpret, summarize, and compress what they see in a single pass. As complexity increases, they lose global consistency: entities blur together, long-range relationships drop out, and structural fidelity gives way to approximation.
This isn't a limitation of model intelligence, it's a structural constraint of the approach. Vision-language models are optimized to describe images, not to extract formal representations of systems. When you ask them to process a 150-node architecture diagram, they're doing visual interpretation at every step. There's no mechanism to maintain global consistency as local complexity increases.
Rather than processing a diagram in a single pass, Prime uses a multi-stage extraction pipeline that first builds a structured representation of components and containers, then separately resolves relationships and flows. This allows the system to maintain global consistency even as local complexity increases.
In short: most models are diagram readers. Prime is a system modeler.
Why accurate architecture understanding matters for threat modeling
This distinction matters because architecture understanding is not an academic exercise.
Teams increasingly need AI systems that can reason about architectures before code exists, across hundreds of concurrent initiatives, and without losing consistency as development velocity increases. If a system cannot preserve architectural structure beyond small diagrams, it cannot reliably support design-stage reasoning at scale.
Consider what breaks when architecture understanding fails:
- Threat models miss critical data flows because the model dropped edges
- Security reviews produce inconsistent guidance on similar architectures
- Risk assessments fail to account for trust boundaries that weren't extracted
- Teams lose confidence in AI-assisted analysis and revert to manual review
At 30% - 50% accuracy, automated threat modeling isn't just less useful, it's actively harmful. Engineers stop trusting security guidance, and security teams spend more time debugging bad outputs than they save from automation.
Conclusion: What it takes to understand architecture at scale
The takeaway is not that LLMs are "bad at diagrams." It's that understanding architecture requires persistent, structured system reasoning, not just visual interpretation.
Most AI systems were built to interpret and describe. Prime was built to model and reason. This experiment makes that difference measurable.
The challenge wasn't incremental, it required rethinking how architectural understanding works. General-purpose models will continue to improve at visual interpretation, but the structural problem remains: treating diagrams as images to describe rather than systems to model means accuracy collapses as complexity grows.
Prime solved this by building extraction pipelines that preserve structure first, then resolve relationships within that structure. The result is consistent accuracy on large, complex diagrams at scales where other approaches break down entirely.
For organizations adopting AI-driven development or trying to scale threat modeling and security design reviews, this matters immediately. The architecture diagrams you already use to reason about systems need to be something AI can reliably understand, not approximately, but structurally. Otherwise, design-stage security remains bottlenecked by manual review, and the gap between development velocity and security coverage continues to widen.
We didn't benchmark architecture diagram understanding to show that Prime is better at reading images. We did it to demonstrate that understanding architecture at scale requires fundamentally different approaches, and that those approaches now exist.
The AI Trap: Why ChatGPT Can't Scale Your Threat Modeling Program
Most security teams are already using AI in threat modeling and security design reviews. They just don't always say it out loud.
It starts informally. A PRD gets pasted into ChatGPT to get oriented before a review. An LLM is asked to summarize a messy Jira epic or extract data flows from a half-written document. A threat model gets sanity-checked after the fact. Not because it's "AI-driven security," but because unstructured design data practically demands it.
Threat modeling has always lived in unstructured inputs: incomplete docs, diagrams that lag reality, tickets that describe intent indirectly. LLMs are simply very good at working with this kind of material. Once teams experience that leverage, they don't go back to doing everything manually.
At that point, the question is no longer whether to use AI in threat modeling. It becomes a much more familiar one: do we build this ourselves, or do we adopt a product?
Why are security teams turning to AI for threat modeling?
The forcing function is velocity.
In many organizations, developers can go from idea to production in a day. New services, integrations, and data flows appear continuously. Meanwhile, security design reviews still assume lead time: intake, scheduling, workshops, follow-ups.
A two-week wait for a threat model is no longer a delay. It's a miss.
Security teams feel this pressure immediately. They can either accept shrinking coverage or find a way to compress design-stage feedback without sacrificing quality. That's where AI enters the picture, intentionally or not.
After speaking with hundreds of teams, a consistent pattern emerges in what works and where things break.
How do security teams start using AI for threat modeling?
The first stage is straightforward and surprisingly effective.
Teams use LLMs for one-off design reviews. Paste in a PRD. Ask for threats. Generate a diagram. Sometimes export it to Mermaid to make iteration easier. For individual reviews, this works well. It's faster than starting from a blank page and often surfaces obvious gaps.
For already-overloaded teams, this alone feels like a breakthrough.
But it doesn't scale in a durable way. Every review is isolated. Context is short-lived. Accuracy depends heavily on who is prompting and what they remember to include. Nothing accumulates.
How do you scale AI-assisted security design reviews?
The next step is almost inevitable.
Someone adds retrieval. Policies get indexed. Maybe internal standards too. A dedicated Claude or ChatGPT project appears. Sometimes a lightweight app gets built using tools like Lovable or n8n. There's an integration with Google Docs to generate threat models in place, or a Slack bot to initiate reviews.
For a while, this feels like the answer. Coverage improves. Intake friction drops. The “scale problem” looks solved. Then reality sets in.
Then reality sets in.
The system doesn't remember past decisions well. Context goes stale. Similar designs get different answers. Engineers lose trust as accuracy hovers around "pretty good," which is not good enough for security guidance. At scale, 50% accuracy is worse than none.
This is where most internal efforts stall.
Why is building AI for threat modeling so difficult?
At this stage, teams rediscover an old lesson: automated threat modeling quality is not about generating text. It's about consistent reasoning grounded in shared memory.
To move past this point, you need:
- An accurate, evolving understanding of the product and its architecture
- Durable memory of past decisions, accepted risks, and exceptions
- The ability to reason over large, messy context without hallucinating
That is hard to build. Harder to maintain. And even harder to explain to engineers when it breaks.
But there is a deeper problem that shows up even when the tooling is solid: visibility still depends on developer behavior.
Most internal systems only see work when someone remembers to ask for a review, uses the right template, or triggers the right workflow. Even with AI assistance, coverage is gated by human compliance. In high-velocity environments, that assumption does not hold. Engineers move quickly, patterns repeat, and small design changes accumulate into material risk without ever crossing a formal review boundary.
This is where many threat modeling programs quietly lose control. Not because reviews are low quality, but because security cannot see what never entered the system.
Should you build or buy AI threat modeling tools?
At that point, the buy-versus-build decision becomes unavoidable.
Building is absolutely an option. With enough time, AI expertise, and dedicated security validation, teams can assemble something that works. But it is expensive, fragile, and non-core. You need engineers who understand LLM behavior, infrastructure to manage context and memory, and security practitioners validating outputs continuously.
Everything is possible, the real question is why invest that effort just to regain visibility that should be table stakes.
The decision is not about whether AI-assisted reviews work. It's about whether rebuilding a bespoke AI security system is the best way to restore visibility across all planned work.
This is also why platforms like Prime exist. Not to "do threat modeling," but to observe design-stage change directly from systems of record like Jira and Confluence, maintain context over time, and surface risk whether or not someone explicitly asked for a review.
Why AI alone doesn't solve the threat modeling scale problem
AI didn’t change what good threat modeling requires. It made it obvious where threat modeling breaks at scale. LLMs can analyze design documents and identify threats, and they’re getting better every month. But the limiting factors aren’t analytical. They’re structural.
First, threat modeling depends on institutional memory. Without durable context about your architecture, past decisions, and accepted risk, guidance stays inconsistent and trust never compounds. Every review starts from scratch.
Second, even perfect threat models don’t help if security can’t see the work. Most risk is introduced through tickets, docs, and design changes that never cross a formal review boundary. If AI only activates when developers remember to ask, coverage collapses.
These aren’t problems you solve with better prompts or more RAG. They require persistent context and proactive visibility into planned work.
That’s the real build-versus-buy question. Not whether AI can help with threat modeling, it can, but whether rebuilding institutional memory and visibility from scratch is the best use of a security team’s finite attention when the real challenge is seeing all the design work happening in the first place.