Prime Resources
featured articles
Code Volume Diverged From Headcount. Pricing Must Follow
For most of AppSec's history, developer headcount was the only reliable number available, so it became the number the market priced against. More developers meant more code. More code meant more risk. Seat-based pricing and seat-based TAM models followed, and both held up for over a decade.
They don't anymore. And the TAM is considerably larger than the seat-based spreadsheets suggest.
The market was built on a correlation, not a cause
The old math was clean. As of 2021 there were roughly 28 million developers worldwide, about 60% of them at companies with more than 50 employees. Blend a per-seat price across the usual module set, SAST, SCA, secrets scanning, IaC, ASPM, and you land somewhere around $500 per developer per year. Multiply it out and the AppSec TAM comes to roughly $8.4 billion, projected to climb to around $14 billion by 2030 on the back of 3 to 5% annual headcount growth.
Not bad.
The model made sense because the correlation held. One developer produced roughly one developer's worth of code, so headcount was a fair stand-in for output. The seat was a unit that meant something. Every AppSec pricing page, and most of the TAM decks behind them, still run on that assumption, projecting the market forward by projecting hiring forward.
Five years later, professional developer headcount still grows in the low single digits. Code output left that curve. GitHub processed 986 million commits in 2025, a 25% jump in a single year after a decade of low-teens growth. Platform totals blend many things together, including a record year of new signups, so treat that number as directional.
The per-developer data is where the break shows up. Cursor's usage data shows mean lines added per developer per week climbing from 3.6K to 8.6K in about seventeen months. Lines added per pull request at the 75th percentile are up roughly 2.5x year over year. The growth rate is still accelerating.
Per seat pricing models stopped meaning anything.
Beyond volume, the seat itself stopped functioning as a stable unit. A marketing manager with the right tooling can ship more code in an afternoon than some backend engineers ship in a week. A team of ten, properly equipped, outproduces a team of hundreds running outdated practices. None of it shows up in a headcount projection, because headcount was never measuring output. It was measuring who had a badge and a laptop.
When a badge reliably produced a predictable amount of code, per-seat licensing made sense. Now a single seat can produce zero lines in a week or a thousand in an hour, generated by a swarm of agents running continuously against a codebase. A unit that can represent either reality at any given moment isn't a unit worth pricing against.
Once headcount stops tracking output, pricing products or sizing the market on it stops making sense. Code defines the attack surface, not the developer who happened to be logged in when it was written. Pricing and sizing product security against code produced is a straightforward correction.
The formula changed in five years:
2021: [seats] x [security modules]
2026: [code volume] x [risk]
Run the napkin math and the $14 billion 2030 projection looks conservative. A market growing in the low single digits and a market compounding past 25% a year part company fast. Within a few years they are no longer versions of the same forecast. They are different markets.
Not all code deserves the same scrutiny
The argument comes with an obvious caveat. Raw line counts aren't the whole answer, because all lines aren't created equal. A payment service and an internal dashboard do not deserve the same scan frequency, the same review depth, or the same scrutiny, even if they produce a comparable number of commits in a given week.
The real unit is risk-weighted code: what a change touches, who and what can reach it, how exploitable it is once it ships. Weight the volume by risk and the growth story holds. Risk-weighted volume grows slower than raw lines, since agents generate plenty of scaffolding and tests, but it still compounds an order of magnitude faster than headcount. The caveat narrows the number. It doesn't rescue the seat.
Risk weighting is also why validation matters more than finding count. A scanner that produces more alerts as code volume grows is describing the problem faster, at higher cost. Sizing and pricing against code volume holds up only if the code being counted is weighted by what it can do to the business.
Are we moving to consumption based AppSec?
I can't speak for the market. I can speak for Prime: we priced the product on consumption, because seats no longer count anything. Security context has to follow code and risk, from architecture through code to the running environment. A model priced on seats can't scale with a codebase that no longer scales with people.
If you're a buyer, run the test yourself. Chart your code volume against your headcount for the last eighteen months, then put that chart next to your security invoices. If the invoices track the flat line, you know which market your vendor is pricing. And stop negotiating what counts as an active developer. That fight exists because the unit is fake.
Consumption will cost some buyers more, and that's worth saying out loud. But the spend isn't new. The attack surface grew the moment the code shipped; a seat-based invoice just didn't register it. Risk-weighting keeps the meter honest: scaffolding shouldn't cost what a payment service costs. You pay for the risk you're carrying, which is the only number worth paying against.
Ready to see what it looks like to size and secure your codebase by what it actually produces, not by how many seats are logged in? Learn more at primesec.ai.
Cutting Through ProdSec Noise
Prioritizing Vulnerabilities by Context Driven Attack Paths, Not Severity Score
Open any vulnerability dashboard right now and you'll see the same thing every security team sees: more findings than anyone could review in a lifetime, ranked by severity scores that all cluster near the top. Roughly 48,000 new CVEs were published in 2025 alone, and the average program has bandwidth to remediate somewhere between 10 and 15 percent of its backlog in a given month. That gap between what gets found and what gets fixed isn't a staffing problem. It's noise, and it's been mistaken for a risk picture for long enough that most teams have stopped questioning it.
Vendors have started layering exploitability and reachability signals on top of severity scores, flagging whether a CVE has a known exploit in the wild or whether the vulnerable function is actually called by application code. That's a real step past CVSS alone, and it does cut some findings out of the queue. But exploitability and reachability answer "can this be exploited," not "does it matter here." A reachable, exploitable vulnerability in an internal tool with no sensitive data behind it is a different risk than the identical vulnerability in a service with a direct path to payment data, and exploitability scoring alone can't tell those two apart. Without the business and architectural context to make that distinction, exploitability and reachability data just re-sorts the same pile into a slightly different order. It doesn't reduce it.
Where All This Noise Comes From
Noise doesn't come from one bad scanner. It comes from the fact that every scanner you add reports its own findings in isolation, with no view of whether anything it flags actually connects to anything else. SAST grades code. SCA grades dependencies. Secret scanning grades commits. Each one is doing its job correctly, and each one is contributing its own independent stream of severity-ranked findings to a backlog that was already too large before it showed up.
That fragmentation was survivable when code shipped at human pace. AI coding agents have removed that constraint, and the backlog is growing with it. A developer opens a handful of pull requests a day; an agent working in the background can open dozens, and every one of them triggers its own pass from every scanner in the pipeline. The noise problem stopped being something a team could plan around once a quarter and became something that compounds with every commit an agent makes, which means the case for reducing it is no longer theoretical. It's urgent, and it gets more urgent by the day.
Adding tools to cover more of the stack feels like progress, and in a narrow sense it is. But it also means the noise compounds. Four scanners each reporting cleanly on their own slice of the product doesn't add up to a quieter picture of risk. It adds up to four separate streams of findings, none of which know about the other three, and that isolation is exactly what produces false positives and false confidence in the same breath. A scanner with no view of the environment has no way to know a downstream control already neutralizes what it just flagged, so it reports a real finding as urgent when it isn't. The opposite failure is just as common: without understanding how the surrounding system actually behaves, a tool can't verify whether a vulnerability it found is reachable in an actual attack path, which means genuine risk gets buried in the same pile as the noise around it.
Why More Noise Doesn't Mean More Security
The instinct is to sort the noise by severity and work top-down. That fails because severity measures how bad a vulnerability could theoretically be, not whether it's reachable, exposed, or exploitable in this specific environment. Two findings with identical CVSS scores can carry completely different risk depending on what's around them: one sits behind three layers of controls, the other has a direct path to production. A backlog sorted by severity alone treats those as the same problem, which is exactly why teams burn remediation capacity on findings that were never going anywhere while genuinely dangerous ones sit untouched further down the list.
Cutting Through the Noise Starts with One Question
Cutting through that noise isn't a matter of triaging faster or tuning the scoring model harder. It requires asking a different question of every finding, one severity scores were never built to answer: is this part of a path an attacker could actually walk right now, given what it connects to. And more importantly, how feasible is this path? If an exploit requires Tom Cruise to dangle dramatically from the ceiling, it’s unlikely to be prioritized by attackers. In other words, there is no simple solution that relies on a single score…which is exactly why context matters!
That's an execution-path question, not a severity question, and it changes what "important" means. A CVSS 9.8 sitting on a service with no route to anything sensitive isn't urgent, whatever the score says. A medium-severity finding sitting on a component that connects straight to a trust boundary might be the most important thing in the backlog. Severity describes a finding in isolation. An execution path describes what happens once you stop looking at scores and start focusing on the real impact to the business and how exposed the vertical to that impact.
What's Left When You Filter for Execution Paths
Run that filter honestly and the backlog doesn't just get shorter, it changes shape entirely. What's left isn't a smaller version of the same list sorted the same way. It's a small, specific set of findings that are reachable and chained together into something an attacker could actually use, the kind of path where a component that passes its own scan cleanly still turns out to be one link in a route to something that matters.
Building a Practice Around Signal, Not Volume
None of this is an argument for buying another scanner. Another scanner adds another stream of severity-ranked findings, which is exactly the problem, not the fix. What's needed is something that doesn't produce its own isolated list at all: a way of seeing the product as one connected system, where a finding is judged by what it opens up rather than scored and filed on its own.
SAST, SCA, and secret scanning were built to grade their own slice of the product well, not to reason across slices, and no amount of tuning changes that. What's missing is a layer above all of them, one that holds architecture, data flows, and access paths in view together and asks the question none of the individual scanners can: does this finding sit on a path an attacker could really walk, given everything else true about this product right now.
The Elephant in the Room: Developer Alert Fatigue
The noise problem doesn't stay in security's backlog. Every finding that reaches a developer without context asks them to stop and chase down whether it's real, and often it isn't: a downstream control already handles it, the path doesn't exist, the function isn't even called. After enough of those empty chases, the rational response isn't more diligence. It's discounting the next finding, and the one after that.
That erosion is the real cost. It isn't just inefficient for security teams triaging a backlog. It teaches developers, correctly, that most of what lands in their queue isn't worth their time, which means the findings that actually matter now have to fight through that learned skepticism to get acted on at all. The fix isn't more findings or sterner tickets. It's surfacing only what's already been checked against the path it would need to travel.
What This Means for Security Leaders
The measure of a good vulnerability management practice was never how many findings you closed this quarter. It's whether what's left in front of your team, after the noise is filtered out, is actually worth their time. A shorter list sorted by the same broken signal isn't progress. A list built from real execution paths, however short, is.
At Prime, this is the case for correlating findings against real execution paths across the whole product rather than triaging them one severity score at a time, so what reaches your team is what an attacker could actually walk, not everything a scanner happened to flag.
Ready to see what's left once the noise is filtered out? Learn more at primesec.ai.
Software Security Needs a New Unit to Review
For the last decade, the pull request has been the moment a developer's work paused long enough for someone else to look at it. That pause is what turned the PR into a checkpoint. A reviewer read the diff and checked it for whatever could go wrong: bugs, broken business logic, security holes. Nobody designed the PR to be a security control. It became one because it was the last place in the software lifecycle where a person reliably paid attention before code shipped.
Now agentic development is breaking the math that made the diff work. PRs are getting bigger and more frequent at the same time, and the pause they run through hasn't gotten any longer. The unit of review is shifting under security's feet.
Before anyone scanned PRs, security tools ran against whole repositories, and compliance programs accepted that as review. The results were unusable: thousands of noisy findings and no way to tell which ones mattered. So the industry moved down to the diff. It was the easiest unit to work with, not the right one.
The PR is changing. Drastically.
Look at what a pull request is actually made of: a diff, a comment thread, and an approval button. None of it was ever the control. It was just tooling built for the moment someone paused to review the work. The pause survived on three conditions. PRs stayed small enough to read closely. Rare enough that every one of them got read. And the review produced a handful of issues that a developer will actually fix.
Agentic development is killing all three at once. Cursor's enterprise data shows average PR size more than doubling, with volume up another 25% on top. Mega PRs, 1,000 lines or more, are now routine. A Microsoft study of Claude Code and GitHub Copilot CLI users found adopters merging roughly 24% more PRs, hitting 50% in heavy-use weeks and holding there for four months. And bigger PRs carry more issues per review, pushing every comment thread past the point where developers stop reading it.
Any one of these would strain a review built around a careful pause. Together they take away everything it needed: time per PR, few enough PRs to give each one that time, and findings scarce enough to get fixed.
What's actually inside all those new PRs
Volume is only half the problem. The other half is what's landing inside each PR. CodeRabbit's analysis of AI-co-authored pull requests found they carry roughly 1.7 times more issues than human-only PRs, including 1.5 to 2 times more security-relevant findings like improper credential handling and insecure object references. High-issue outliers cluster in AI-assisted work. So a reviewer doesn't know which PR needed the slow read until they've already skimmed past it.
Compliance programs accept PR approvals as evidence that changes were reviewed before deployment. Today, the audit trail looks exactly like it did three years ago. What's changed is what that approval means. It used to mean someone read the code. Now, on a 1,500-line agent-written PR that arrived with six others that morning, it mostly means the person ran out of reasons to keep it open. The requirement is still being met on paper. Whether real security is happening underneath is a separate question, and no audit is built to ask it.
The unit was always a proxy
Once you see the PR as a stand-in for attention rather than a control in its own right, the question changes. Scaling review to handle more, bigger PRs is the wrong project. The real question is where that attention needs to live now that it can't all sit in one checkpoint.
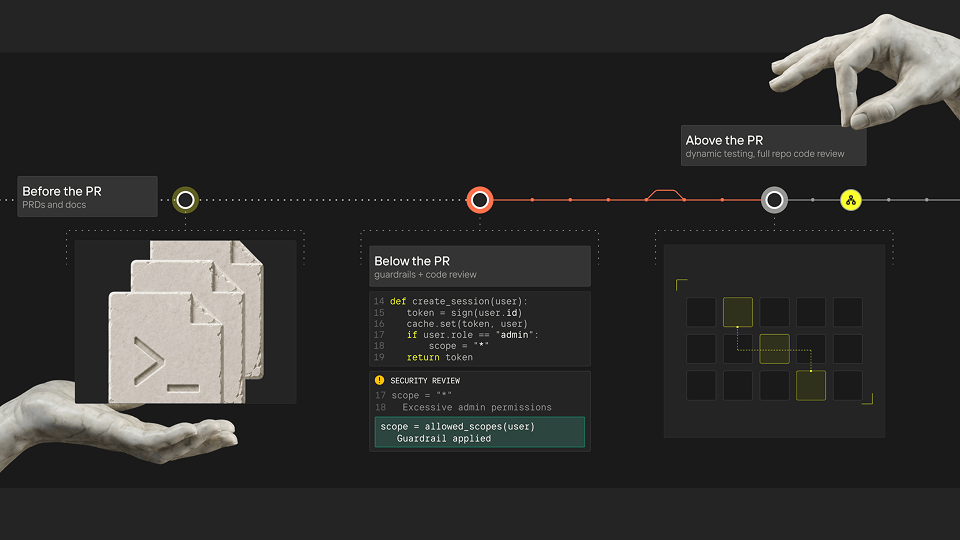
Some of it belongs below the PR, where an agent makes decisions in real time and context can be applied before a diff exists. Some belongs above it, at the repository level, because a vulnerability spread across several small, reasonable PRs never shows up in any single diff. And some belongs before the PR entirely, in the architecture and design decisions that shape what an agent, or a developer, can build in the first place.
The repository level is the one that should give people pause, because the industry has been there before. Repo-wide analysis is where this story started, and it collapsed under its own findings. But that was a context problem, not a level problem. The tools flagged patterns without knowing what was reachable, what was exploitable, or what mattered to the product. Analysis that traces attack vectors and validates exploitability before it surfaces anything produces the one thing the old scanners never could: a short list. Five findings a developer will actually fix, with a risk score that is attached to a product. The comment-count condition, restored at the level the industry abandoned.
So PR reviews are dead? Right? Right?
No, PR reviews aren't dead. The pause they measured is.
Reviews stay in the program as one place security happens, not the primary one. Attention has to live where decisions live now: in the design before code exists, in the code as it's written, in the repository as it evolves. This is what we do at Prime, that's the architecture: review the design, guard the code, trace attack vectors across the repo, dependencies, and cloud continuously.
Code Volume Diverged From Headcount. Pricing Must Follow
For most of AppSec's history, developer headcount was the only reliable number available, so it became the number the market priced against. More developers meant more code. More code meant more risk. Seat-based pricing and seat-based TAM models followed, and both held up for over a decade.
They don't anymore. And the TAM is considerably larger than the seat-based spreadsheets suggest.
The market was built on a correlation, not a cause
The old math was clean. As of 2021 there were roughly 28 million developers worldwide, about 60% of them at companies with more than 50 employees. Blend a per-seat price across the usual module set, SAST, SCA, secrets scanning, IaC, ASPM, and you land somewhere around $500 per developer per year. Multiply it out and the AppSec TAM comes to roughly $8.4 billion, projected to climb to around $14 billion by 2030 on the back of 3 to 5% annual headcount growth.
Not bad.
The model made sense because the correlation held. One developer produced roughly one developer's worth of code, so headcount was a fair stand-in for output. The seat was a unit that meant something. Every AppSec pricing page, and most of the TAM decks behind them, still run on that assumption, projecting the market forward by projecting hiring forward.
Five years later, professional developer headcount still grows in the low single digits. Code output left that curve. GitHub processed 986 million commits in 2025, a 25% jump in a single year after a decade of low-teens growth. Platform totals blend many things together, including a record year of new signups, so treat that number as directional.
The per-developer data is where the break shows up. Cursor's usage data shows mean lines added per developer per week climbing from 3.6K to 8.6K in about seventeen months. Lines added per pull request at the 75th percentile are up roughly 2.5x year over year. The growth rate is still accelerating.
Per seat pricing models stopped meaning anything.
Beyond volume, the seat itself stopped functioning as a stable unit. A marketing manager with the right tooling can ship more code in an afternoon than some backend engineers ship in a week. A team of ten, properly equipped, outproduces a team of hundreds running outdated practices. None of it shows up in a headcount projection, because headcount was never measuring output. It was measuring who had a badge and a laptop.
When a badge reliably produced a predictable amount of code, per-seat licensing made sense. Now a single seat can produce zero lines in a week or a thousand in an hour, generated by a swarm of agents running continuously against a codebase. A unit that can represent either reality at any given moment isn't a unit worth pricing against.
Once headcount stops tracking output, pricing products or sizing the market on it stops making sense. Code defines the attack surface, not the developer who happened to be logged in when it was written. Pricing and sizing product security against code produced is a straightforward correction.
The formula changed in five years:
2021: [seats] x [security modules]
2026: [code volume] x [risk]
Run the napkin math and the $14 billion 2030 projection looks conservative. A market growing in the low single digits and a market compounding past 25% a year part company fast. Within a few years they are no longer versions of the same forecast. They are different markets.
Not all code deserves the same scrutiny
The argument comes with an obvious caveat. Raw line counts aren't the whole answer, because all lines aren't created equal. A payment service and an internal dashboard do not deserve the same scan frequency, the same review depth, or the same scrutiny, even if they produce a comparable number of commits in a given week.
The real unit is risk-weighted code: what a change touches, who and what can reach it, how exploitable it is once it ships. Weight the volume by risk and the growth story holds. Risk-weighted volume grows slower than raw lines, since agents generate plenty of scaffolding and tests, but it still compounds an order of magnitude faster than headcount. The caveat narrows the number. It doesn't rescue the seat.
Risk weighting is also why validation matters more than finding count. A scanner that produces more alerts as code volume grows is describing the problem faster, at higher cost. Sizing and pricing against code volume holds up only if the code being counted is weighted by what it can do to the business.
Are we moving to consumption based AppSec?
I can't speak for the market. I can speak for Prime: we priced the product on consumption, because seats no longer count anything. Security context has to follow code and risk, from architecture through code to the running environment. A model priced on seats can't scale with a codebase that no longer scales with people.
If you're a buyer, run the test yourself. Chart your code volume against your headcount for the last eighteen months, then put that chart next to your security invoices. If the invoices track the flat line, you know which market your vendor is pricing. And stop negotiating what counts as an active developer. That fight exists because the unit is fake.
Consumption will cost some buyers more, and that's worth saying out loud. But the spend isn't new. The attack surface grew the moment the code shipped; a seat-based invoice just didn't register it. Risk-weighting keeps the meter honest: scaffolding shouldn't cost what a payment service costs. You pay for the risk you're carrying, which is the only number worth paying against.
Ready to see what it looks like to size and secure your codebase by what it actually produces, not by how many seats are logged in? Learn more at primesec.ai.
Cutting Through ProdSec Noise
Prioritizing Vulnerabilities by Context Driven Attack Paths, Not Severity Score
Open any vulnerability dashboard right now and you'll see the same thing every security team sees: more findings than anyone could review in a lifetime, ranked by severity scores that all cluster near the top. Roughly 48,000 new CVEs were published in 2025 alone, and the average program has bandwidth to remediate somewhere between 10 and 15 percent of its backlog in a given month. That gap between what gets found and what gets fixed isn't a staffing problem. It's noise, and it's been mistaken for a risk picture for long enough that most teams have stopped questioning it.
Vendors have started layering exploitability and reachability signals on top of severity scores, flagging whether a CVE has a known exploit in the wild or whether the vulnerable function is actually called by application code. That's a real step past CVSS alone, and it does cut some findings out of the queue. But exploitability and reachability answer "can this be exploited," not "does it matter here." A reachable, exploitable vulnerability in an internal tool with no sensitive data behind it is a different risk than the identical vulnerability in a service with a direct path to payment data, and exploitability scoring alone can't tell those two apart. Without the business and architectural context to make that distinction, exploitability and reachability data just re-sorts the same pile into a slightly different order. It doesn't reduce it.
Where All This Noise Comes From
Noise doesn't come from one bad scanner. It comes from the fact that every scanner you add reports its own findings in isolation, with no view of whether anything it flags actually connects to anything else. SAST grades code. SCA grades dependencies. Secret scanning grades commits. Each one is doing its job correctly, and each one is contributing its own independent stream of severity-ranked findings to a backlog that was already too large before it showed up.
That fragmentation was survivable when code shipped at human pace. AI coding agents have removed that constraint, and the backlog is growing with it. A developer opens a handful of pull requests a day; an agent working in the background can open dozens, and every one of them triggers its own pass from every scanner in the pipeline. The noise problem stopped being something a team could plan around once a quarter and became something that compounds with every commit an agent makes, which means the case for reducing it is no longer theoretical. It's urgent, and it gets more urgent by the day.
Adding tools to cover more of the stack feels like progress, and in a narrow sense it is. But it also means the noise compounds. Four scanners each reporting cleanly on their own slice of the product doesn't add up to a quieter picture of risk. It adds up to four separate streams of findings, none of which know about the other three, and that isolation is exactly what produces false positives and false confidence in the same breath. A scanner with no view of the environment has no way to know a downstream control already neutralizes what it just flagged, so it reports a real finding as urgent when it isn't. The opposite failure is just as common: without understanding how the surrounding system actually behaves, a tool can't verify whether a vulnerability it found is reachable in an actual attack path, which means genuine risk gets buried in the same pile as the noise around it.
Why More Noise Doesn't Mean More Security
The instinct is to sort the noise by severity and work top-down. That fails because severity measures how bad a vulnerability could theoretically be, not whether it's reachable, exposed, or exploitable in this specific environment. Two findings with identical CVSS scores can carry completely different risk depending on what's around them: one sits behind three layers of controls, the other has a direct path to production. A backlog sorted by severity alone treats those as the same problem, which is exactly why teams burn remediation capacity on findings that were never going anywhere while genuinely dangerous ones sit untouched further down the list.
Cutting Through the Noise Starts with One Question
Cutting through that noise isn't a matter of triaging faster or tuning the scoring model harder. It requires asking a different question of every finding, one severity scores were never built to answer: is this part of a path an attacker could actually walk right now, given what it connects to. And more importantly, how feasible is this path? If an exploit requires Tom Cruise to dangle dramatically from the ceiling, it’s unlikely to be prioritized by attackers. In other words, there is no simple solution that relies on a single score…which is exactly why context matters!
That's an execution-path question, not a severity question, and it changes what "important" means. A CVSS 9.8 sitting on a service with no route to anything sensitive isn't urgent, whatever the score says. A medium-severity finding sitting on a component that connects straight to a trust boundary might be the most important thing in the backlog. Severity describes a finding in isolation. An execution path describes what happens once you stop looking at scores and start focusing on the real impact to the business and how exposed the vertical to that impact.
What's Left When You Filter for Execution Paths
Run that filter honestly and the backlog doesn't just get shorter, it changes shape entirely. What's left isn't a smaller version of the same list sorted the same way. It's a small, specific set of findings that are reachable and chained together into something an attacker could actually use, the kind of path where a component that passes its own scan cleanly still turns out to be one link in a route to something that matters.
Building a Practice Around Signal, Not Volume
None of this is an argument for buying another scanner. Another scanner adds another stream of severity-ranked findings, which is exactly the problem, not the fix. What's needed is something that doesn't produce its own isolated list at all: a way of seeing the product as one connected system, where a finding is judged by what it opens up rather than scored and filed on its own.
SAST, SCA, and secret scanning were built to grade their own slice of the product well, not to reason across slices, and no amount of tuning changes that. What's missing is a layer above all of them, one that holds architecture, data flows, and access paths in view together and asks the question none of the individual scanners can: does this finding sit on a path an attacker could really walk, given everything else true about this product right now.
The Elephant in the Room: Developer Alert Fatigue
The noise problem doesn't stay in security's backlog. Every finding that reaches a developer without context asks them to stop and chase down whether it's real, and often it isn't: a downstream control already handles it, the path doesn't exist, the function isn't even called. After enough of those empty chases, the rational response isn't more diligence. It's discounting the next finding, and the one after that.
That erosion is the real cost. It isn't just inefficient for security teams triaging a backlog. It teaches developers, correctly, that most of what lands in their queue isn't worth their time, which means the findings that actually matter now have to fight through that learned skepticism to get acted on at all. The fix isn't more findings or sterner tickets. It's surfacing only what's already been checked against the path it would need to travel.
What This Means for Security Leaders
The measure of a good vulnerability management practice was never how many findings you closed this quarter. It's whether what's left in front of your team, after the noise is filtered out, is actually worth their time. A shorter list sorted by the same broken signal isn't progress. A list built from real execution paths, however short, is.
At Prime, this is the case for correlating findings against real execution paths across the whole product rather than triaging them one severity score at a time, so what reaches your team is what an attacker could actually walk, not everything a scanner happened to flag.
Ready to see what's left once the noise is filtered out? Learn more at primesec.ai.
Software Security Needs a New Unit to Review
For the last decade, the pull request has been the moment a developer's work paused long enough for someone else to look at it. That pause is what turned the PR into a checkpoint. A reviewer read the diff and checked it for whatever could go wrong: bugs, broken business logic, security holes. Nobody designed the PR to be a security control. It became one because it was the last place in the software lifecycle where a person reliably paid attention before code shipped.
Now agentic development is breaking the math that made the diff work. PRs are getting bigger and more frequent at the same time, and the pause they run through hasn't gotten any longer. The unit of review is shifting under security's feet.
Before anyone scanned PRs, security tools ran against whole repositories, and compliance programs accepted that as review. The results were unusable: thousands of noisy findings and no way to tell which ones mattered. So the industry moved down to the diff. It was the easiest unit to work with, not the right one.
The PR is changing. Drastically.
Look at what a pull request is actually made of: a diff, a comment thread, and an approval button. None of it was ever the control. It was just tooling built for the moment someone paused to review the work. The pause survived on three conditions. PRs stayed small enough to read closely. Rare enough that every one of them got read. And the review produced a handful of issues that a developer will actually fix.
Agentic development is killing all three at once. Cursor's enterprise data shows average PR size more than doubling, with volume up another 25% on top. Mega PRs, 1,000 lines or more, are now routine. A Microsoft study of Claude Code and GitHub Copilot CLI users found adopters merging roughly 24% more PRs, hitting 50% in heavy-use weeks and holding there for four months. And bigger PRs carry more issues per review, pushing every comment thread past the point where developers stop reading it.
Any one of these would strain a review built around a careful pause. Together they take away everything it needed: time per PR, few enough PRs to give each one that time, and findings scarce enough to get fixed.
What's actually inside all those new PRs
Volume is only half the problem. The other half is what's landing inside each PR. CodeRabbit's analysis of AI-co-authored pull requests found they carry roughly 1.7 times more issues than human-only PRs, including 1.5 to 2 times more security-relevant findings like improper credential handling and insecure object references. High-issue outliers cluster in AI-assisted work. So a reviewer doesn't know which PR needed the slow read until they've already skimmed past it.
Compliance programs accept PR approvals as evidence that changes were reviewed before deployment. Today, the audit trail looks exactly like it did three years ago. What's changed is what that approval means. It used to mean someone read the code. Now, on a 1,500-line agent-written PR that arrived with six others that morning, it mostly means the person ran out of reasons to keep it open. The requirement is still being met on paper. Whether real security is happening underneath is a separate question, and no audit is built to ask it.
The unit was always a proxy
Once you see the PR as a stand-in for attention rather than a control in its own right, the question changes. Scaling review to handle more, bigger PRs is the wrong project. The real question is where that attention needs to live now that it can't all sit in one checkpoint.
Some of it belongs below the PR, where an agent makes decisions in real time and context can be applied before a diff exists. Some belongs above it, at the repository level, because a vulnerability spread across several small, reasonable PRs never shows up in any single diff. And some belongs before the PR entirely, in the architecture and design decisions that shape what an agent, or a developer, can build in the first place.
The repository level is the one that should give people pause, because the industry has been there before. Repo-wide analysis is where this story started, and it collapsed under its own findings. But that was a context problem, not a level problem. The tools flagged patterns without knowing what was reachable, what was exploitable, or what mattered to the product. Analysis that traces attack vectors and validates exploitability before it surfaces anything produces the one thing the old scanners never could: a short list. Five findings a developer will actually fix, with a risk score that is attached to a product. The comment-count condition, restored at the level the industry abandoned.
So PR reviews are dead? Right? Right?
No, PR reviews aren't dead. The pause they measured is.
Reviews stay in the program as one place security happens, not the primary one. Attention has to live where decisions live now: in the design before code exists, in the code as it's written, in the repository as it evolves. This is what we do at Prime, that's the architecture: review the design, guard the code, trace attack vectors across the repo, dependencies, and cloud continuously.
Black-Box Pentesting Gives Attackers the Advantage
For years, black-box penetration testing has relied on a simple premise: simulate an attacker who knows nothing about the system. The tester starts outside the application, discovers endpoints and functionality, infers architecture, and gradually builds an understanding of how the product works.
That assumption is outdated.
A serious attacker already has more information than the traditional black-box model assumes. Source code routinely leaves organizations through compromised insiders, contractors, repositories, legitimate access obtained under false pretenses, and AI-assisted development workflows. Source secrecy is no longer a strong foundation for offensive security.
If applications need to remain secure when an adversary understands how they work, testing needs to begin from the same vantage point. That is attacker parity.
Source code leaves through ordinary access
Source-code theft does not require a dramatic breach.
The North Korean IT worker campaign illustrates the problem. The FBI has warned that DPRK IT workers use false identities to obtain legitimate employment with U.S. companies and then use that access to steal proprietary information. In January 2025, the FBI specifically warned that workers had held stolen source code and other proprietary data for ransom.
Google Threat Intelligence has documented the same campaign at significant scale. The important security lesson is how access is obtained. An attacker hired under a false identity receives credentials, repository access, internal communications, and the same development environment as other employees. From the application's perspective, that access is legitimate.
AI-assisted development creates another path. Developers now work across coding assistants, model APIs, IDE extensions, autonomous agents, and third-party development services. When proprietary code is submitted to an external AI service, that service becomes part of the system trusted with the code. NIST's Generative AI Profile identifies data privacy, information security, third-party components, and data governance as areas organizations need to manage when deploying generative AI.
Source confidentiality is a weak assumption for an offensive security strategy.
Black-box testing assumes attacker ignorance
A black-box tester spends part of every engagement reconstructing information the engineering organization already possesses. They discover APIs, map routes, infer trust boundaries, experiment with authentication flows, and probe application behavior to understand the architecture.
That work is useful when the objective is to measure what an outsider discovers from an exposed application. It is a limited model of what a capable adversary does.
Source access changes the economics of attacking an application. Reconnaissance is faster, hypotheses are easier to form, and security controls are inspected directly instead of inferred through trial and error. Authorization logic, hidden endpoints, dependency behavior, and implementation assumptions all become easier to investigate.
The attacker spends more time searching for exploitable weaknesses while the black-box tester spends valuable engagement time rediscovering how the product works.
We already accept this model with open-source software. Security controls in an open-source application must withstand attackers who can inspect the implementation. Proprietary applications deserve the same standard.
White-box testing creates attacker parity
Defenders already possess an extraordinary amount of useful security context. They have the source code, architecture, security requirements, dependencies, deployment model, and historical design decisions.
White-box penetration testing puts that context to work.
A tester who understands the implementation moves directly into deeper questions about exploitability. They trace authorization logic across services, follow data through trust boundaries, examine how security controls are implemented, and identify places where implementation differs from design intent.
That context also makes it easier to investigate attack paths rather than isolated findings. A minor authorization weakness becomes critical when combined with a particular identity path or cloud configuration. Source code provides only part of that picture. Effective Product Security testing also needs architectural context, identity, infrastructure, dependencies, and application behavior.
A capable attacker uses whatever information they obtain. Defenders should use the information they already own.
Attacker parity must continue as the product changes
A white-box assessment still represents a point in time. The application starts changing again as soon as the engagement ends.
New code lands, dependencies change, APIs evolve, infrastructure is modified, and authorization logic gets refactored. AI coding tools and development agents have accelerated software production and increased the volume of changes security teams need to understand.
Attackers keep studying the product as it evolves. Offensive security needs the same continuity.
Continuous white-box pentesting preserves application context and repeatedly evaluates what is actually exploitable as the product changes. At Prime, that means connecting code with architecture, dependencies, cloud resources, application behavior, security decisions, and attack paths so testing starts with the context required to investigate meaningful risk.
Black-box testing still has a role
Black-box testing remains useful for understanding what an unauthenticated or opportunistic outsider discovers. It tests externally observable attack surface and exposes weaknesses in authentication, configuration, discovery, and application behavior.
It should not define the upper bound of an offensive security program.
A motivated adversary has source code, internal documentation, credentials, architecture details, or extensive time to study how the product works. Your security team already has more context than that.
Use it.
Treat source access as part of the threat model, give testers the information advantage available to defenders, and test applications from the perspective of an informed adversary.
Ready to see how Prime continuously tests applications with the same product context an informed attacker would? Learn more at primesec.ai.
Prime introduces a new operating model for Product Security
Prime Security today introduced a new operating model for Product Security, expanding its platform to help security teams participate in every product decision - from architecture and design through implementation and continuous validation.
The announcement comes as the company returns to Black Hat USA, one year after winning the conference's prestigious Startup Spotlight competition, where it will showcase the expanded platform this week in Las Vegas.
Prime's expanded platform addresses a fundamental change in how software is built. As AI accelerates engineering and compresses the distance between architecture, implementation, and deployment, security can no longer rely on reviewing finished code alone. It must participate continuously as products are designed, built, and shipped.
From day one, Prime has taken a different approach to Product Security. Rather than analyzing isolated pieces of software, the platform was built to understand products as complete systems - starting with architecture and design decisions, where critical security context is created long before code is written.
That architectural foundation now extends across the entire product lifecycle, enabling security teams to participate before the code, in the code, and after the code through a shared understanding of the product.
The expanded platform includes autonomous design reviews, AI security code reviews, AI coding guardrails, risk-focused software supply chain security, and continuous white-box pentesting - all powered by the same understanding of the product and its architecture.
Prime CEO Michael Nov said:
"Software development has fundamentally changed. Architecture, implementation, and deployment no longer happen as separate phases - they increasingly happen together, often inside the same AI-assisted workflow. Security can't keep up by reviewing software after it's built because the important decisions have already been made. Product Security has to participate as those decisions are being made. That's what Prime was built for."
Backed by Foundation Capital, Flybridge and Scale Venture Partners, Prime is trusted by organizations including PayPal, Bumble, Qualtrics, MX, and ThoughtSpot among its customers.
Customers report completing security design reviews in as little as 15 minutes, increasing security team capacity by 4-5x, and reducing false positives by up to 90% compared to traditional application security approaches.
Learn more at https://www.primesec.ai or visit https://www.primesec.ai/blackhat-2026 for Black Hat activities and event information.

Before the Code. In the Code. After the Code. Security in the age of AI Factories
Software development didn't just get faster. It broke shape. The old shape of plan, design, build, test, deploy is not how software gets built anymore. Now it is specs in one place, prompts in another, code written by humans and agents, architecture decisions made in a chat window, and tests generated after the fact.
The boundary around who builds is dissolving too. Engineers orchestrate agents. Product managers turn ideas into real products with the help of vibe coding. Business Analysts build workflows that touch real data and real systems. Some of it enters the formal SDLC. Some never do. All of it changes the attack surface.
The end state is becoming obvious: software factories run mostly by agents, the way lights-out factories run manufacturing lines with no humans on the floor. Some companies are already there. Most are in the awkward middle - partial adoption, uneven quality, and pressure to move faster anyway.
Strip away the noise and the goal is simple: whatever reaches production has to be secure and follow the rules you set for it. That job did not change. Everything around it did.
Shift left and DevSecOps were the right answers for their moment - but both were designed around developers making decisions. Now agents make architectural choices, wire data flows, and push work forward faster than any human checkpoint can follow. Every prompt, every PR, every agent-generated feature is an architectural decision your security team never reviewed.
The next model is not a faster human. It is an autonomous security agent operating in the same environment as the development agents - and it cannot work component by component. Attackers already don't: AI-powered attack tooling chains the design flaws, code vulnerabilities, and cloud misconfigs your agents just introduced into single exploitable paths. Scanners see files. Pipelines see changes. Attackers see weaknesses - and need only one that connects. Security has to see the product - that is where weaknesses connect: what is being planned, what is in work, and what has shipped.
That is what Product Security means now. Not security embedded in a pipeline - security as an autonomous participant in it, holding the product view through every stage: before the code, in it, and after it.
Before the code - where intent gets set and attack vectors get introduced
For business critical features and complex systems, design still deserves real scrutiny before a single line gets written. An agent factory executing a flawed design quickly is worse than a slow team building the wrong thing manually. The blast radius is bigger. A missing auth requirement, a broken tenant isolation model, an exposed data flow - these are not code problems. They are design decisions, and agents execute them at speed.
As spec-driven development matures, getting the spec right becomes the highest-leverage security investment you can make. The old way of getting it right was threat modeling - a workshop, a whiteboard, an architect asking the right questions. It worked, for the handful of features that got one. That trade dies when a product manager's spec becomes running code in a day. Autonomous review changes the economics: it reads every spec, ticket, and PRD as it is written - wherever intent lives - and asks what the architect would have asked.
What the design stage gives you is the missing context: what the feature is meant to do, who should reach it, what data it touches, and what it must never allow. Without that, the check after the code can only answer one question: is this vulnerable? With it, it can answer the ones that actually drive a decision: does this vulnerability matter, what does it cost the business, and is this what was supposed to get built?
Design is still where security starts. It is no longer where it stops. The review does not produce just a report. It produces the context the next stage runs on.
In the code - security cannot just guide agents. It has to act.
Prompts change. Models change. Agents change. The system is what accumulates - every architecture decision, every trust boundary, every data flow, every intent, layered over years. Without that context, a security agent can reason about code. With it, it can reason about the system.
Security has two jobs here: steer the work while it is written, and gate it before it merges.
Steering happens in the moment. A development agent starts wiring a new data flow - the security agent loads the live architecture, reads the trust boundaries, and if something is wrong, intervenes. Not a flag. Not a ticket. An agent with the authority to block a bad decision before it is ever committed.
The gate is the pull request - the last moment a change is still just a proposed change. Everything gets checked, every time, no matter who or what wrote the code. The gate answers one question: does this change violate a rule you already set? Hardcoded secrets, broken cryptography, and prohibited patterns do not require system-wide reasoning. They are known violations and should be stopped immediately. That is what makes the gate fast, deterministic, and difficult to argue with. Exploitability is a different question.
The PR merges. The change becomes part of the system. And exploitability lives in the system, not the diff.
After the code - where exploitable paths get validated
The change has landed. It is part of a system now. Whether it is exploitable is no longer a fact about the change - it is a fact about the system around it. The gate answered one question: did you break a rule. This stage answers the other: is there a path to exploit. The analysis starts the moment the change lands, before anything ships, and it never stops after.
First, at the repo level. A flagged line of code matters only if it plays a part in an attack path - as the way in, or as a step along the way - past the controls that exist. A vulnerable dependency only matters if the vulnerable function is reachable and exploitable with input an attacker controls. Part of no path is noise. That is how the 200-issue queue dies - validation eliminates the 195 that never mattered and confirms the five that did.
Then at the system level, continuously. Clean when it landed does not mean clean today: a new CVE drops against a dependency you merged six months ago, a cloud config drifts, another team's change opens a path through your service. The attacker does not care which PR introduced which piece - only whether a path exists through the system as it runs right now.
You hold the source, the architecture, the cloud controls, and the intent behind every feature - everything an attacker wishes they had, and you have it first. Run the real thing from the inside: continuous, white-box attack path analysis across the live system. An internal service skips authentication because nothing external can reach it. An agent builds on its API, a routing change exposes it - zero findings, one path to customer data. Only the intent recorded on day one makes the last change light up.
Not is this vulnerable - a scanner guesses at that. Is there an exploitable path, through this architecture, past these controls, into this data. You do not infer it. You validate it. The output is not a list of findings. It is a path an attacker can take, end to end.
–
The challenge has shifted. It is no longer "How do we find bugs earlier?" It is "How do we release secure software when the decisions that matter are made autonomously, continuously, and faster than any human review can follow?" That question does not have a checkpoint answer. Security cannot review decisions after they are made. It has to participate in them as they happen.
And participation is not three products at three checkpoints. It is one view of the product - planned, in work, shipped. The intent understood before the code is what makes steering possible during it, and what makes validation credible after it. Break that chain into point tools and each sees a slice; the exploitable path that matters often spans all three. That is not another scanner or another policy engine. It is a new operating model for Product Security.
We built Prime to run that model.
Before the code, it reviews design intent autonomously and records what every feature is supposed to do. In the code, it steers agents and developers with the live architecture loaded, and gates every PR on the rules you set. After the code, it validates exploitable paths continuously across the live system.
This only works as one platform. Prime can validate an exploitable path because it understood what the feature was supposed to do before the code existed, followed how it was implemented, and sees how the system and its controls connect today. That context cannot be reconstructed reliably after the fact. It has to persist from intent through implementation.
The factory is already running. Security can review its decisions after they happen, or participate in them as they are made. We built Prime for the second answer. Before the code. In the code. After the code.
The Most Ignored Artifact in Security is Now the Most Important One
Security policies were the documents nobody read. Written, published, forgotten. Developers worked around them. Security teams rewrote them every two years and called it progress. Everyone understood the game and nobody said anything because it was mostly harmless. A bad policy sat in a wiki somewhere and collected dust.
That is no longer the situation.
In an agentic world the agent does not work around the policy. It follows it. Every time. No judgment, no improvisation, no common sense filling the gaps. That changes what a bad policy costs, in a way most security teams have not fully sat with yet.
A bad policy written for humans is a document nobody reads. Mostly harmless because humans ignored it anyway. A bad policy followed by agents is consistent wrong behavior, at scale, across everything your agents touch. It does not sit in a document anymore. It ships.
Here is what that looks like in practice. A policy that says "use appropriate encryption" is standard language in half the security documents written in the last decade. It tells a human to think and make a reasonable call. It tells an agent to decide. It will decide. It might pick MD5. It will be consistent about it.
The language that felt precise enough for a human audience, "appropriate," "reasonable," "where possible," is not precise at all. It is an instruction to exercise judgment. Rewriting policies for agents forces decisions that security teams have been deferring for years. What does appropriate encryption actually mean in this system? What counts as sensitive data in this context? What should the agent never do, regardless of what it is asked? These questions used to live in someone's head. Now they have to be written down in a form a machine can execute without a human in the loop to catch the edge cases.
The difference in practice looks something like this. The old version says "use appropriate encryption for sensitive data." The new version says "all data classified as sensitive must be encrypted using AES-256-GCM at rest and TLS 1.3 in transit. The agent must not proceed if either condition cannot be verified." One requires a judgment call. The other does not. If you cannot write a test that verifies the agent followed the policy, the policy is not done.
There is one more thing the static policy model never had to confront. The threat landscape does not wait. When a new attack technique gets published, the window between disclosure and active exploitation is sometimes days. A policy that was correct last month can be the thing that gets you next month. Human security teams absorbed that kind of change through awareness, the engineer who read the advisory and updated the standard before it mattered. Agents do not read advisories. They follow what they were given. A policy that cannot be updated dynamically and propagated to every agent consuming it in real time is already becoming a liability the moment it is written. Specificity and machine readability make agent-ready policy powerful. They also make it brittle if the update mechanism is not part of the design from the start.
That is a pipeline problem as much as a content problem. The policy layer has to be live. Version controlled, continuously updated against the current threat landscape, and connected to the agents consuming it in a way that does not require a manual deployment every time something changes. That is new infrastructure most security teams do not have yet and are not building.
That is usually how it goes right before something forces it.
Do it before the agent does something your policy technically allowed.
Preparing Security for the Day of Zero-Touch Development
The security industry has spent three years moving the line.
Code completion would not work, then it did. AI-generated features were off the table, too much state, too much domain knowledge, until that ceiling moved too. At some point this stops being analysis and starts being denial. Full application generation is not a question of if.
To be fair, security people are trained skeptics. Questioning things that seem too easy is the job, and that instinct is usually right. The problem is that the same quality that makes a good security professional, a deep distrust of anything that looks too clean, made this genuinely hard to see coming. The reflex was correct. The situation was just different this time. It happens.
So the question now is whether security is ready. The honest answer is no, and the reason is not what most people assume.
Security was not just built around humans. It was built around human behavior. The invisible judgment calls that happen between a design review and a code review. The developer who remembers what got flagged last sprint. The architect who quietly connects a vulnerability report to the decision that caused it six months earlier. None of that is written down anywhere. It lives in people's heads, and it has for years, because it worked well enough. In most organizations there is a senior engineer who every payments-related finding gets quietly routed to before triage, not because any process says so, but because she is the only one who remembers why a particular call was made in 2019 and what breaks if you touch it. That knowledge is not in any system. It is in her calendar.
Zero-touch development removes those people before most security programs have captured what they know. A dev agent can carry security context, if that context exists somewhere it can reach. The risk is not that agents are blind by nature. It is that most security guidance today is not documented in any form an agent can consume. It is institutional knowledge inside humans who are about to be removed from the loop.
The tools are not too slow. They are islands, and the human who connected them is leaving.
This is the work that has to start now. Not procuring new platforms. Capturing what security teams already know and putting it somewhere agents can actually reach, policy encoded in the pipeline, threat models that live in the repo, guardrail rules derived from the organization's own findings rather than generic frameworks. The difference between an agent that ships secure code and one that does not is almost never the model. It is whether the guidance was there in the first place.
MCP changes something more fundamental than integration. APIs existed before and teams built connectors, but every connection was a custom project, owned by someone, maintained by someone, and when that someone left it quietly broke. MCP makes the connectivity layer a shared standard rather than a collection of bespoke plumbing, so the loop stays closed without a human constantly holding it together. But the architecture is only as good as what goes into it. Connectivity does not fix a documentation problem. Those are two different problems and it is worth being clear about which one you are solving.
The policy layer behind all of this cannot sit in AppSec alone. AppSec owns the enforcement and the enablement, the guardrails, the pipeline controls, the agent-level guidance. But the policy itself has to be built across security, engineering and GRC together. That is not a coordination challenge to be managed. That is the actual work.
The window is open right now. Once zero-touch development is fully running, retrofitting security guidance into a process already operating without it is slower, more expensive and always one step behind. The teams doing this work today are not just getting ahead of a trend. They are building the institutional memory their agents will run on.
The ones waiting are not just behind. They are losing the people who know the things that cannot be recovered.
Most Developers Will Not Understand Security in 5 Years
Developers are already shipping code they didn't write and couldn't fully explain. They described what they wanted and an agent built it. That's not a criticism, it's just the next abstraction layer, same as every one before it. Assembly to C. C to Python. Python to "hey Claude, build me this feature."
Each time we abstract, we gain speed and lose depth. That is the tradeoff. Nobody complains that developers do not write assembly anymore.
But here is the thing nobody in security wants to say: if a developer does not really understand how the code works, they definitely do not understand how secure it is. And we are all kind of tiptoeing around that.
The old DevSecOps model was already barely holding. Developers would write the code, security would run a scanner, get a report that says "SQL injection, line 84," and try to get the developer who wrote line 84 to go fix it while praying that the finding is relevant. It was clunky and slow but it worked because there was a human who had context.
What happens when a human is not the one who wrote line 84? When the diff is 3,000 lines and it came from an agent interpreting a Jira ticket?
Throwing a CVE report at the developer guiding the agent is almost a joke. They don't know what the agent was thinking. Neither do you. And that is in the easy case of a SAST or dependency finding - what if the risk is a chain of lows across multiple repos, or an architectural flaw? This is bound to fail.
This doesn’t mean security goes away, it just has to find a new home in this process.
It is not the developer who needs to know security anymore. It is the agent. Security teams have to get in front of it at the design stage, defining what the agent should do and how it should do it according to how the organization actually works. Then enforce that during the build with guardrails - think prompt-level policy enforcement, tool-call allow-listing, and output scanning - that keep the agent on track in real time. And then test. Nobody is ready to let agents just run unsupervised, compliance won't allow it and, honestly, common sense won't either. Testing is how security teams verify that none of that went wrong. No vulnerabilities, no compliance gaps, no drift from the guidance the agent was given.
Which means the full process looks pretty familiar: guide the agent upfront, give it secure guardrails, test the output. Same thing security teams tried to do with developers for twenty years. Except developers argued back. Agents do not.
There is a consequence to that nobody is talking about yet. Every security and compliance framework assumes you can trace a decision back to a person. When something ships with a vulnerability today there is a chain: who wrote it, who reviewed it, who approved it. When an agent wrote it, that chain dissolves. The agent does not remember its reasoning. The developer did not write the code. Everyone was involved and nobody is accountable. That means the audit trail has to move from people to systems. Agent actions logged, decisions traceable, guidance on record. Not for compliance theater. Because when something goes wrong that record is the only chain left.
And the guidance has to be right. If the security context the agent receives is wrong or incomplete, it will faithfully reproduce the flaw at scale, across every repo, every feature, every team using that agent. That is not a lower bar than the old model. It is a considerably higher one.
Security teams that get this have a real opportunity right now. Not to slow things down, that ship has sailed, but to finally be at the table when the rules get written. The business is moving to agents whether security is ready or not. The only question is whether security shapes how those agents are built, or spends the next decade cleaning up after them.